Publications
Full list on Google Scholar
Published papers, preprints, books, patents, reports, and dissertation. * Equal contribution. † Corresponding author.
51 records
No publications match these filters.
Vision-Language Models and Video Understanding
-
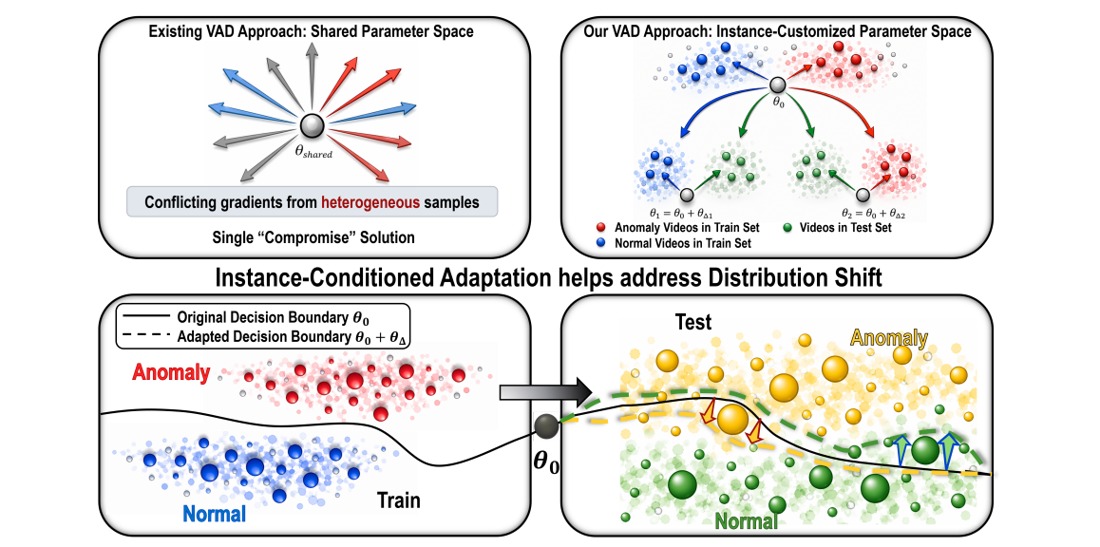
COPRA: Conditional Parameter Adaptation with Reinforcement Learning for Video Anomaly Detection
Conference on Neural Information Processing Systems (NeurIPS), 2026
Main-track acceptance rate: 25.7%
Vision-language models (VLMs) have shown strong performance in video anomaly detection (VAD) while providing interpretable predictions. However, existing VLM-based VAD methods suffer from a fundamental mismatch between training and inference in both data distribution and model configuration. First, most approaches rely on static post-training adaptation, limiting generalization under distribution shifts such as unseen environments or anomaly types. Second, they train VLMs on sparse frames from long videos, but perform inference on densely sampled short segments, creating inconsistencies between training and testing. To address these limitations, we propose COPRA, a conditional parameter adaptation framework for VLM-based VAD. Instead of fixed prompts or shared parameter updates, COPRA generates input-specific parameter updates to dynamically adapt a frozen VLM for each video segment during both training and inference. Experiments show strong performance on standard VAD benchmarks, consistently outperforming static baselines in both in-domain and cross-domain settings. Moreover, COPRA generalizes beyond VAD to unseen tasks such as multiple-choice Video Question Answering and Dense Captioning. These results highlight COPRA as an effective weight-space generation framework for scalable, adaptive, and context-aware video understanding. The code will be released at https://github.com/THE-MALT-LAB/COPRA
@inproceedings{panhe-copra-2026, title = {COPRA: Conditional Parameter Adaptation with Reinforcement Learning for Video Anomaly Detection}, author = {Darryl Cherian Jacob and Xinyu Liu and Kai Wang and Pan He}, year = {2026}, booktitle = {Conference on Neural Information Processing Systems (NeurIPS)}, url = {https://arxiv.org/abs/2605.15325} } -
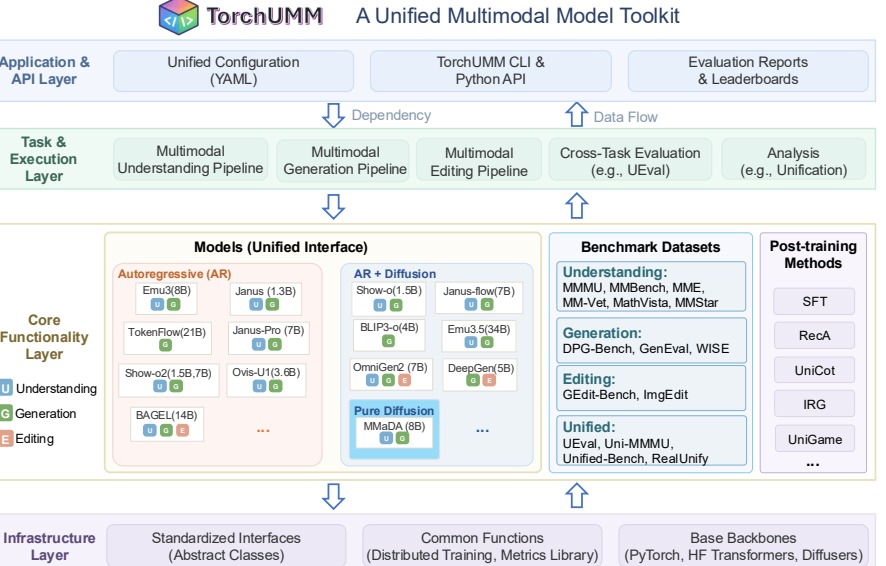
TorchUMM: A Unified Multimodal Model Codebase for Evaluation, Analysis, and Post-training
Conference on Neural Information Processing Systems (NeurIPS), 2026
Main-track acceptance rate: 25.7%
Recent advances in unified multimodal models (UMMs) have led to a proliferation of architectures capable of understanding, generating, and editing across visual and textual modalities. However, developing a unified framework for UMMs remains challenging due to the diversity of model architectures and the heterogeneity of training paradigms and implementation details. In this paper, we present TorchUMM, the first unified codebase for comprehensive evaluation, analysis, and post-training across diverse UMM backbones, tasks, and datasets. TorchUMM supports a broad spectrum of models covering a wide range of scales and design paradigms. Our benchmark encompasses three core task dimensions: multimodal understanding, generation, and editing, and integrates both established and novel datasets to evaluate perception, reasoning, compositionality, and instruction-following abilities. By providing a unified interface and standardized evaluation protocols, TorchUMM enables fair and reproducible comparisons across heterogeneous models and fosters deeper insights into their strengths and limitations, facilitating the development of more capable unified multimodal systems. Code is available at: https://github.com/AIFrontierLab/TorchUMM.
@inproceedings{panhe-torchumm-2026, title = {TorchUMM: A Unified Multimodal Model Codebase for Evaluation, Analysis, and Post-training}, author = {Yinyi Luo and Wenwen Wang and Hayes Bai and Hongyu Zhu and Hao Chen and Pan He and Marios Savvides and Sharon Li and Jindong Wang}, year = {2026}, booktitle = {Conference on Neural Information Processing Systems (NeurIPS)}, url = {https://arxiv.org/abs/2604.10784} } -
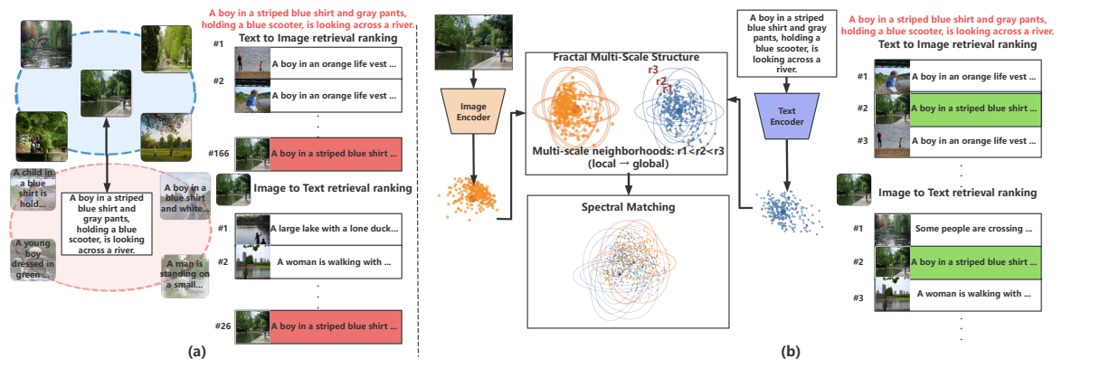
Mitigating the Modality Gap in Vision–Language Models with Fractal Spectral Geometry
International Conference on Machine Learning (ICML), 2026
@inproceedings{panhe-fsalign-2026, title = {Mitigating the Modality Gap in Vision–Language Models with Fractal Spectral Geometry}, author = {Zihan Zhou and Yang Zhou and Ruoming Jin and Pan He and Patrick Emami}, year = {2026}, booktitle = {International Conference on Machine Learning (ICML)}, url = {https://proceedings.mlr.press/v306/zhou26br.html} } -
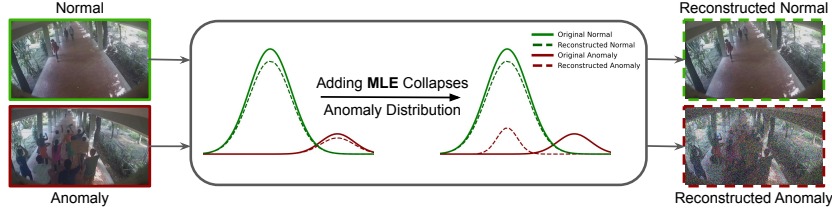
MLE-UVAD: Minimal Latent Entropy Autoencoder for Fully Unsupervised Video Anomaly Detection
arXiv preprint, 2026
In this paper, we address the challenging problem of single-scene, fully unsupervised video anomaly detection (VAD), where raw videos containing both normal and abnormal events are used directly for training and testing without any labels. This differs sharply from prior work that either requires extensive labeling (fully or weakly supervised) or depends on normal-only videos (one-class classification), which are vulnerable to distribution shifts and contamination. We propose an entropy-guided autoencoder that detects anomalies through reconstruction error by reconstructing normal frames well while making anomalies reconstruct poorly. The key idea is to combine the standard reconstruction loss with a novel Minimal Latent Entropy (MLE) loss in the autoencoder. Reconstruction loss alone maps normal and abnormal inputs to distinct latent clusters due to their inherent differences, but also risks reconstructing anomalies too well to detect. Therefore, MLE loss addresses this by minimizing the entropy of latent embeddings, encouraging them to concentrate around high-density regions. Since normal frames dominate the raw video, sparse anomalous embeddings are pulled into the normal cluster, so the decoder emphasizes normal patterns and produces poor reconstructions for anomalies. This dual-loss design produces a clear reconstruction gap that enables effective anomaly detection. Extensive experiments on two widely used benchmarks and a challenging self-collected driving dataset demonstrate that our method achieves robust and superior performance over baselines.
@misc{panhe-mle-uvad-2026, title = {MLE-UVAD: Minimal Latent Entropy Autoencoder for Fully Unsupervised Video Anomaly Detection}, author = {Yuang Geng and Junkai Zhou and Kang Yang and Pan He and Zhuoyang Zhou and Jose C Principe and Joel Harley and Ivan Ruchkin}, year = {2026}, note = {arXiv preprint, 2026}, url = {https://arxiv.org/abs/2603.23868} } -
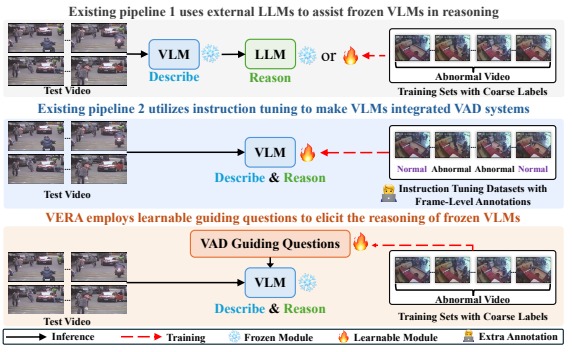
VERA: Explainable Video Anomaly Detection via Verbalized Learning of Vision-Language Models
IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR), 2025
@inproceedings{panhe-vera-2025, title = {VERA: Explainable Video Anomaly Detection via Verbalized Learning of Vision-Language Models}, author = {Muchao Ye and Weiyang Liu and Pan He}, year = {2025}, booktitle = {IEEE/CVF Conference on Computer Vision and Pattern Recognition (CVPR)}, url = {https://openaccess.thecvf.com/content/CVPR2025/html/Ye_VERA_Explainable_Video_Anomaly_Detection_via_Verbalized_Learning_of_Vision-Language_CVPR_2025_paper.html} } -
Preview pending
Two are Better than One: Uncertainty-Aware Vision-Language Models for Video Anomaly Detection
Research manuscript, 2025
Vision-language models (VLMs) have demonstrated impressive reasoning capability in visual understanding tasks. One recent highlight of VLMs is their success in generating human-understandable explanations in video anomaly detection (VAD), which is an advanced video understanding task requiring delicate judgment on context-dependent and ambiguous video content. Representative works mainly formulate this problem as a natural language generation task conditioned on task-related prompts and visual inputs. However, under this paradigm, the input is processed segment by segment, and VLMs generate a response for each segment independently, which inevitably leads to uncertainty in their reasoning with a limited context. To bridge this fundamental gap, we propose an uncertainty-aware VLM framework named Una for VAD to objectively identify the reasoning-level uncertainty in VLMs and correspondingly mitigate it: Firstly, Una obtains relevant scenes by temporal and semantic relevance and determines the existence of uncertainty by the prediction consistency across relevant scenes. After that, collective intelligence via the cooperation of VLMs is introduced to address the uncertainty. With Una, VLMs can achieve remarkable performance and advanced explainability, surpassing task-specific methods in challenging benchmarks in the most difficult setting where instruction tuning is not allowed for the first time.
@misc{panhe-2better-2025, title = {Two are Better than One: Uncertainty-Aware Vision-Language Models for Video Anomaly Detection}, author = {Muchao Ye and Haomiao Ni and Xianren Zhang and Weiyang Liu and Pan He}, year = {2025}, note = {Research manuscript, 2025}, url = {https://openreview.net/forum?id=d7YpJuV64J} } -
Preview pending
VERA++: Advancing Video Anomaly Detection with Uncertainty-Aware Verbalized Learning
Under review, 2025
@misc{panhe-vera-plus-2025, title = {VERA++: Advancing Video Anomaly Detection with Uncertainty-Aware Verbalized Learning}, author = {Muchao Ye and Weiyang Liu and Pan He}, year = {2025}, note = {Under review, 2025}, url = {https://scholar.google.com/citations?view_op=view_citation&user=Y_ABdTgAAAAJ&citation_for_view=Y_ABdTgAAAAJ:-_dYPAW6P2MC} }
Language Models and Reasoning
-
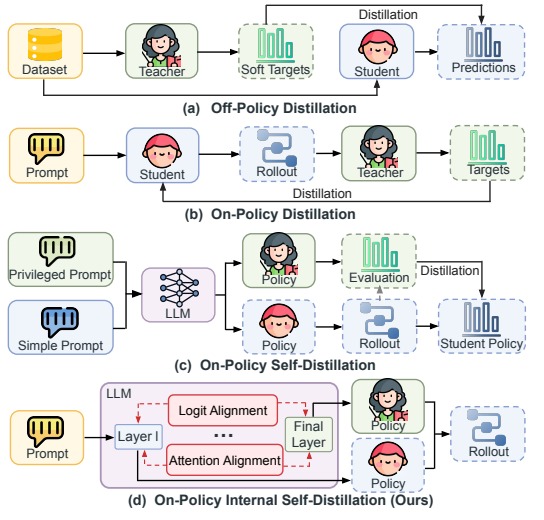
OISD: On-Policy Internal Self-Distillation of Language Models
Findings of the Association for Computational Linguistics: Conference on Empirical Methods in Natural Language Processing (EMNLP), 2026
Findings acceptance rate: 14.3%
Recent reinforcement learning (RL) post-training approaches primarily optimize the final output policy using sparse outcome-level rewards, while largely overlooking predictive signals encoded in intermediate representations. In this paper, we introduce a new paradigm called on-policy internal self-distillation and propose the OISD framework, which improves reasoning by transferring on-policy predictive signals from the final layer to intermediate representations. During rollout and Group Relative Policy Optimization (GRPO) optimization, the final layer acts as both the policy and a detached internal teacher for selected intermediate layers, which are guided to align with it through two complementary mechanisms: logit alignment, which transfers high-level reasoning behaviors (how to think), and attention alignment, which enforces consistent attention patterns (where to look) from the final layer to the selected intermediate layer, both without requiring external privileged information. Our OISD, together with GRPO, employs signed advantage-weighted Jensen–Shannon alignment to distill informative intermediate representations while preserving policy consistency under a unified acting policy. Experimental results demonstrate the effectiveness of OISD, with substantial and consistent improvements over strong reasoning RL baselines across four mathematical reasoning tasks.
@inproceedings{panhe-oisd-2026, title = {OISD: On-Policy Internal Self-Distillation of Language Models}, author = {Xinyu Liu and Darryl Cherian Jacob and Yang Zhou and Jindong Wang and Pan He}, year = {2026}, booktitle = {Findings of the Association for Computational Linguistics: Conference on Empirical Methods in Natural Language Processing (EMNLP)}, url = {https://aclanthology.org/2026.findings-emnlp.1323/} }
Time Series and Recommendation
-
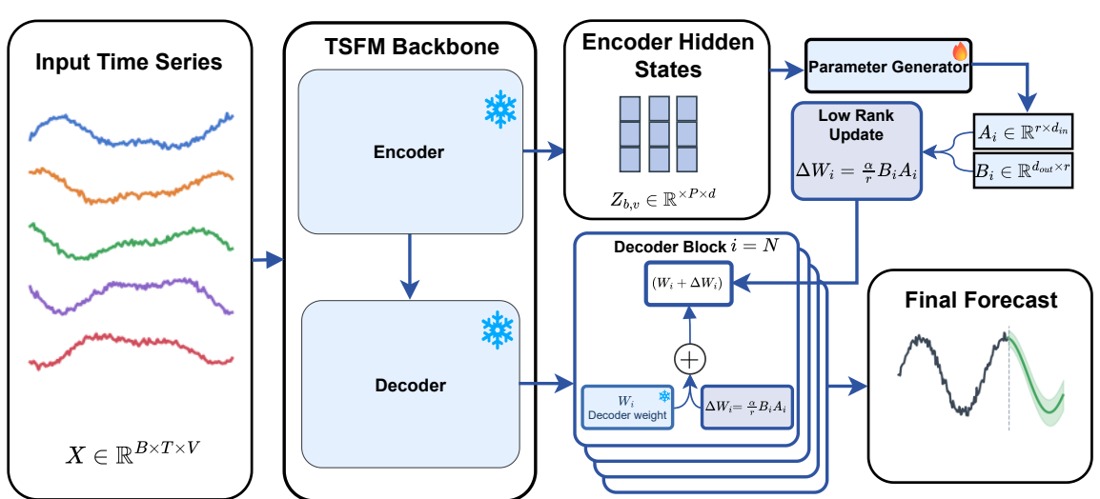
AdaCast: Conditional Parameter Generation for Adaptive Time Series Forecasting
arXiv preprint, 2026
Time-series foundation models (TSFMs) have achieved strong forecasting performance across domains. However, most adaptation methods remain static. Existing all-in-one methods learn a single set of dataset-level parameter updates and apply the same adapted model to every input. As a result, they cannot adapt the model parameters to the temporal patterns, seasonality and dynamics of each input time series. This limits their ability to produce forecasts that are tailored to heterogeneous inputs. To address this limitation, we propose AdaCast, a conditional parameter generation framework for time-series forecasting. AdaCast uses a generator to produce input-specific low-rank parameter updates for a frozen pretrained TSFM. These updates adapt the model to each input during both training and inference. Across six public benchmarks, AdaCast consistently outperforms static adaptation baseline in in-domain forecasting and improves zero-shot generalization to held-out datasets across domains. These results demonstrate that conditional parameter generation provides an effective approach for adaptive forecasting.
@misc{panhe-adacast-2026, title = {AdaCast: Conditional Parameter Generation for Adaptive Time Series Forecasting}, author = {Darahaas Nallagatla and Darryl Cherian Jacob and Pan He}, year = {2026}, note = {arXiv preprint, 2026}, url = {https://arxiv.org/abs/2610.12240} } -
Preview pending
RECAP: Reconstructing the Past to Predict the Future in Time-Series Foundation Models
Under review, 2026
@misc{panhe-recap-2026, title = {RECAP: Reconstructing the Past to Predict the Future in Time-Series Foundation Models}, author = {Darahaas Nallagatla and Darryl Cherian Jacob and Pan He}, year = {2026}, note = {Under review, 2026}, url = {https://scholar.google.com/citations?view_op=view_citation&user=Y_ABdTgAAAAJ&citation_for_view=Y_ABdTgAAAAJ:ipzZ9siozwsC} } -
Preview pending
HiWaveRec: Hierarchical Wavelet Decoupling Framework with Adaptive Gating for Sequential Recommendation
European Conference on Machine Learning and Principles and Practice of Knowledge Discovery in Databases (ECML PKDD), 2026
Research-track acceptance rate: 24.3%
@inproceedings{panhe-hiwaverec-2026, title = {HiWaveRec: Hierarchical Wavelet Decoupling Framework with Adaptive Gating for Sequential Recommendation}, author = {Xuefeng Zhang and Zhengbiao Wu and Chenxin Liu and Jingfan Tang and Guitao Yu and Rui He and Pan He}, year = {2026}, booktitle = {European Conference on Machine Learning and Principles and Practice of Knowledge Discovery in Databases (ECML PKDD)}, url = {https://link.springer.com/chapter/10.1007/978-3-032-37670-1_12} }
Spatiotemporal Point Cloud Processing
-
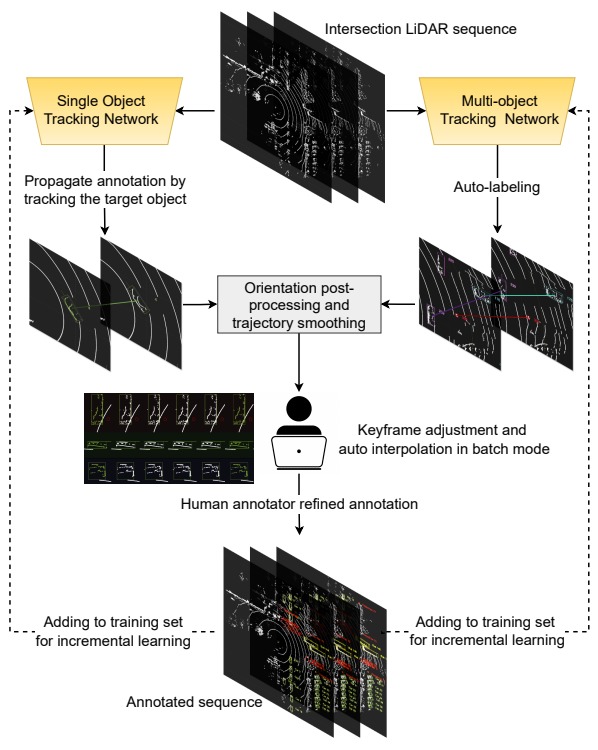
An Efficient Semi-Automated Scheme for Infrastructure LiDAR Annotation
IEEE Transactions on Intelligent Transportation Systems (T-ITS), 2024
Most existing perception systems rely on sensory data acquired from cameras, which perform poorly in low light and adverse weather conditions. To resolve this limitation, we have witnessed advanced LiDAR sensors become popular in perception tasks in autonomous driving applications. Nevertheless, their usage in traffic monitoring systems is less ubiquitous. We identify two significant obstacles in cost-effectively and efficiently developing such a LiDAR-based traffic monitoring system: (i) public LiDAR datasets are insufficient for supporting perception tasks in infrastructure systems, and (ii) 3D annotations on LiDAR point clouds are time-consuming and expensive. To fill this gap, we present an efficient semi-automated annotation tool that automatically annotates LiDAR sequences with tracking algorithms while offering a fully annotated infrastructure LiDAR dataset -- FLORIDA (Florida LiDAR-based Object Recognition and Intelligent Data Annotation) -- which will be made publicly available. Our advanced annotation tool seamlessly integrates multi-object tracking (MOT), single-object tracking (SOT), and suitable trajectory post-processing techniques. Specifically, we introduce a human-in-the-loop schema in which annotators recursively fix and refine annotations imperfectly predicted by our tool and incrementally add them to the training dataset to obtain better SOT and MOT models. By repeating the process, we significantly increase the overall annotation speed by three to four times and obtain better qualitative annotations than a state-of-the-art annotation tool. The human annotation experiments verify the effectiveness of our annotation tool. In addition, we provide detailed statistics and object detection evaluation results for our dataset in serving as a benchmark for perception tasks at traffic intersections.
@article{panhe-florida-2024, title = {An Efficient Semi-Automated Scheme for Infrastructure LiDAR Annotation}, author = {Aotian Wu and Pan He and Xiao Li and Ke Chen and Sanjay Ranka and Anand Rangarajan}, year = {2024}, journal = {IEEE Transactions on Intelligent Transportation Systems (T-ITS)}, url = {https://ieeexplore.ieee.org/abstract/document/10537073/} } -
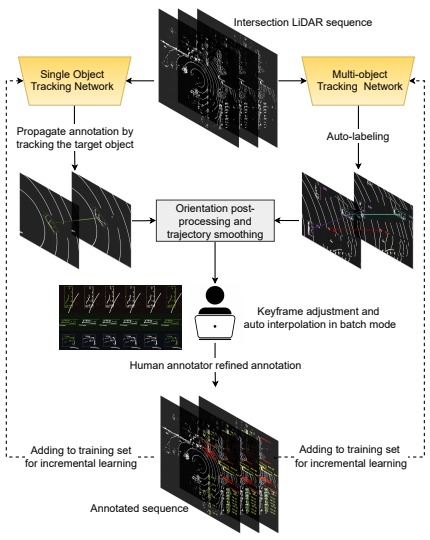
An Efficient Semi-Automated Scheme for LiDAR Annotation and A Benchmark Infrastructure Dataset
Machine Learning for IoT: Datasets, Perception, and Understanding (ML4IoT) Workshop at the International Conference on Learning Representations (ICLR), 2023
@inproceedings{panhe-florida-workshop-2023, title = {An Efficient Semi-Automated Scheme for LiDAR Annotation and A Benchmark Infrastructure Dataset}, author = {Aotian Wu and Pan He and Xiao Li and Ke Chen and Sanjay Ranka and Anand Rangarajan}, year = {2023}, booktitle = {Machine Learning for IoT: Datasets, Perception, and Understanding (ML4IoT) Workshop at the International Conference on Learning Representations (ICLR)}, url = {resources/florida_iclr.pdf} } -
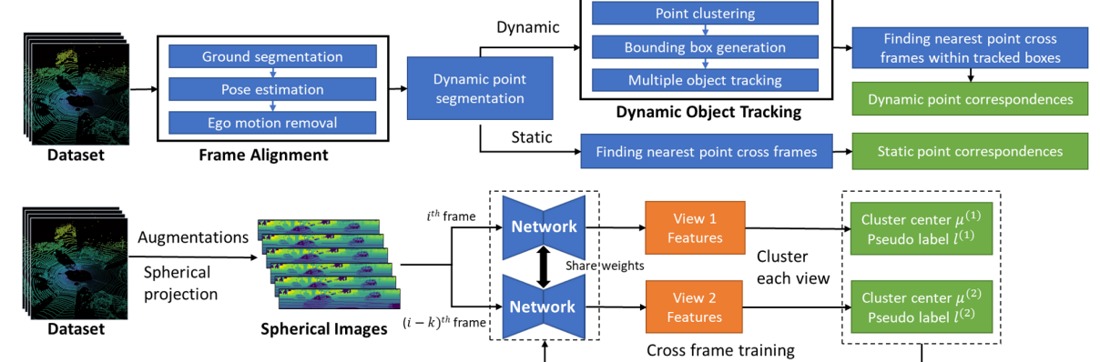
A Spatiotemporal Correspondence Approach to Unsupervised LiDAR Segmentation with Traffic Applications
IEEE International Conference on Intelligent Transportation Systems (ITSC), 2023
@inproceedings{panhe-lidar-seg-2023, title = {A Spatiotemporal Correspondence Approach to Unsupervised LiDAR Segmentation with Traffic Applications}, author = {Xiao Li and Pan He and Aotian Wu and Sanjay Ranka and Anand Rangarajan}, year = {2023}, booktitle = {IEEE International Conference on Intelligent Transportation Systems (ITSC)}, url = {https://arxiv.org/abs/2308.12433} } -
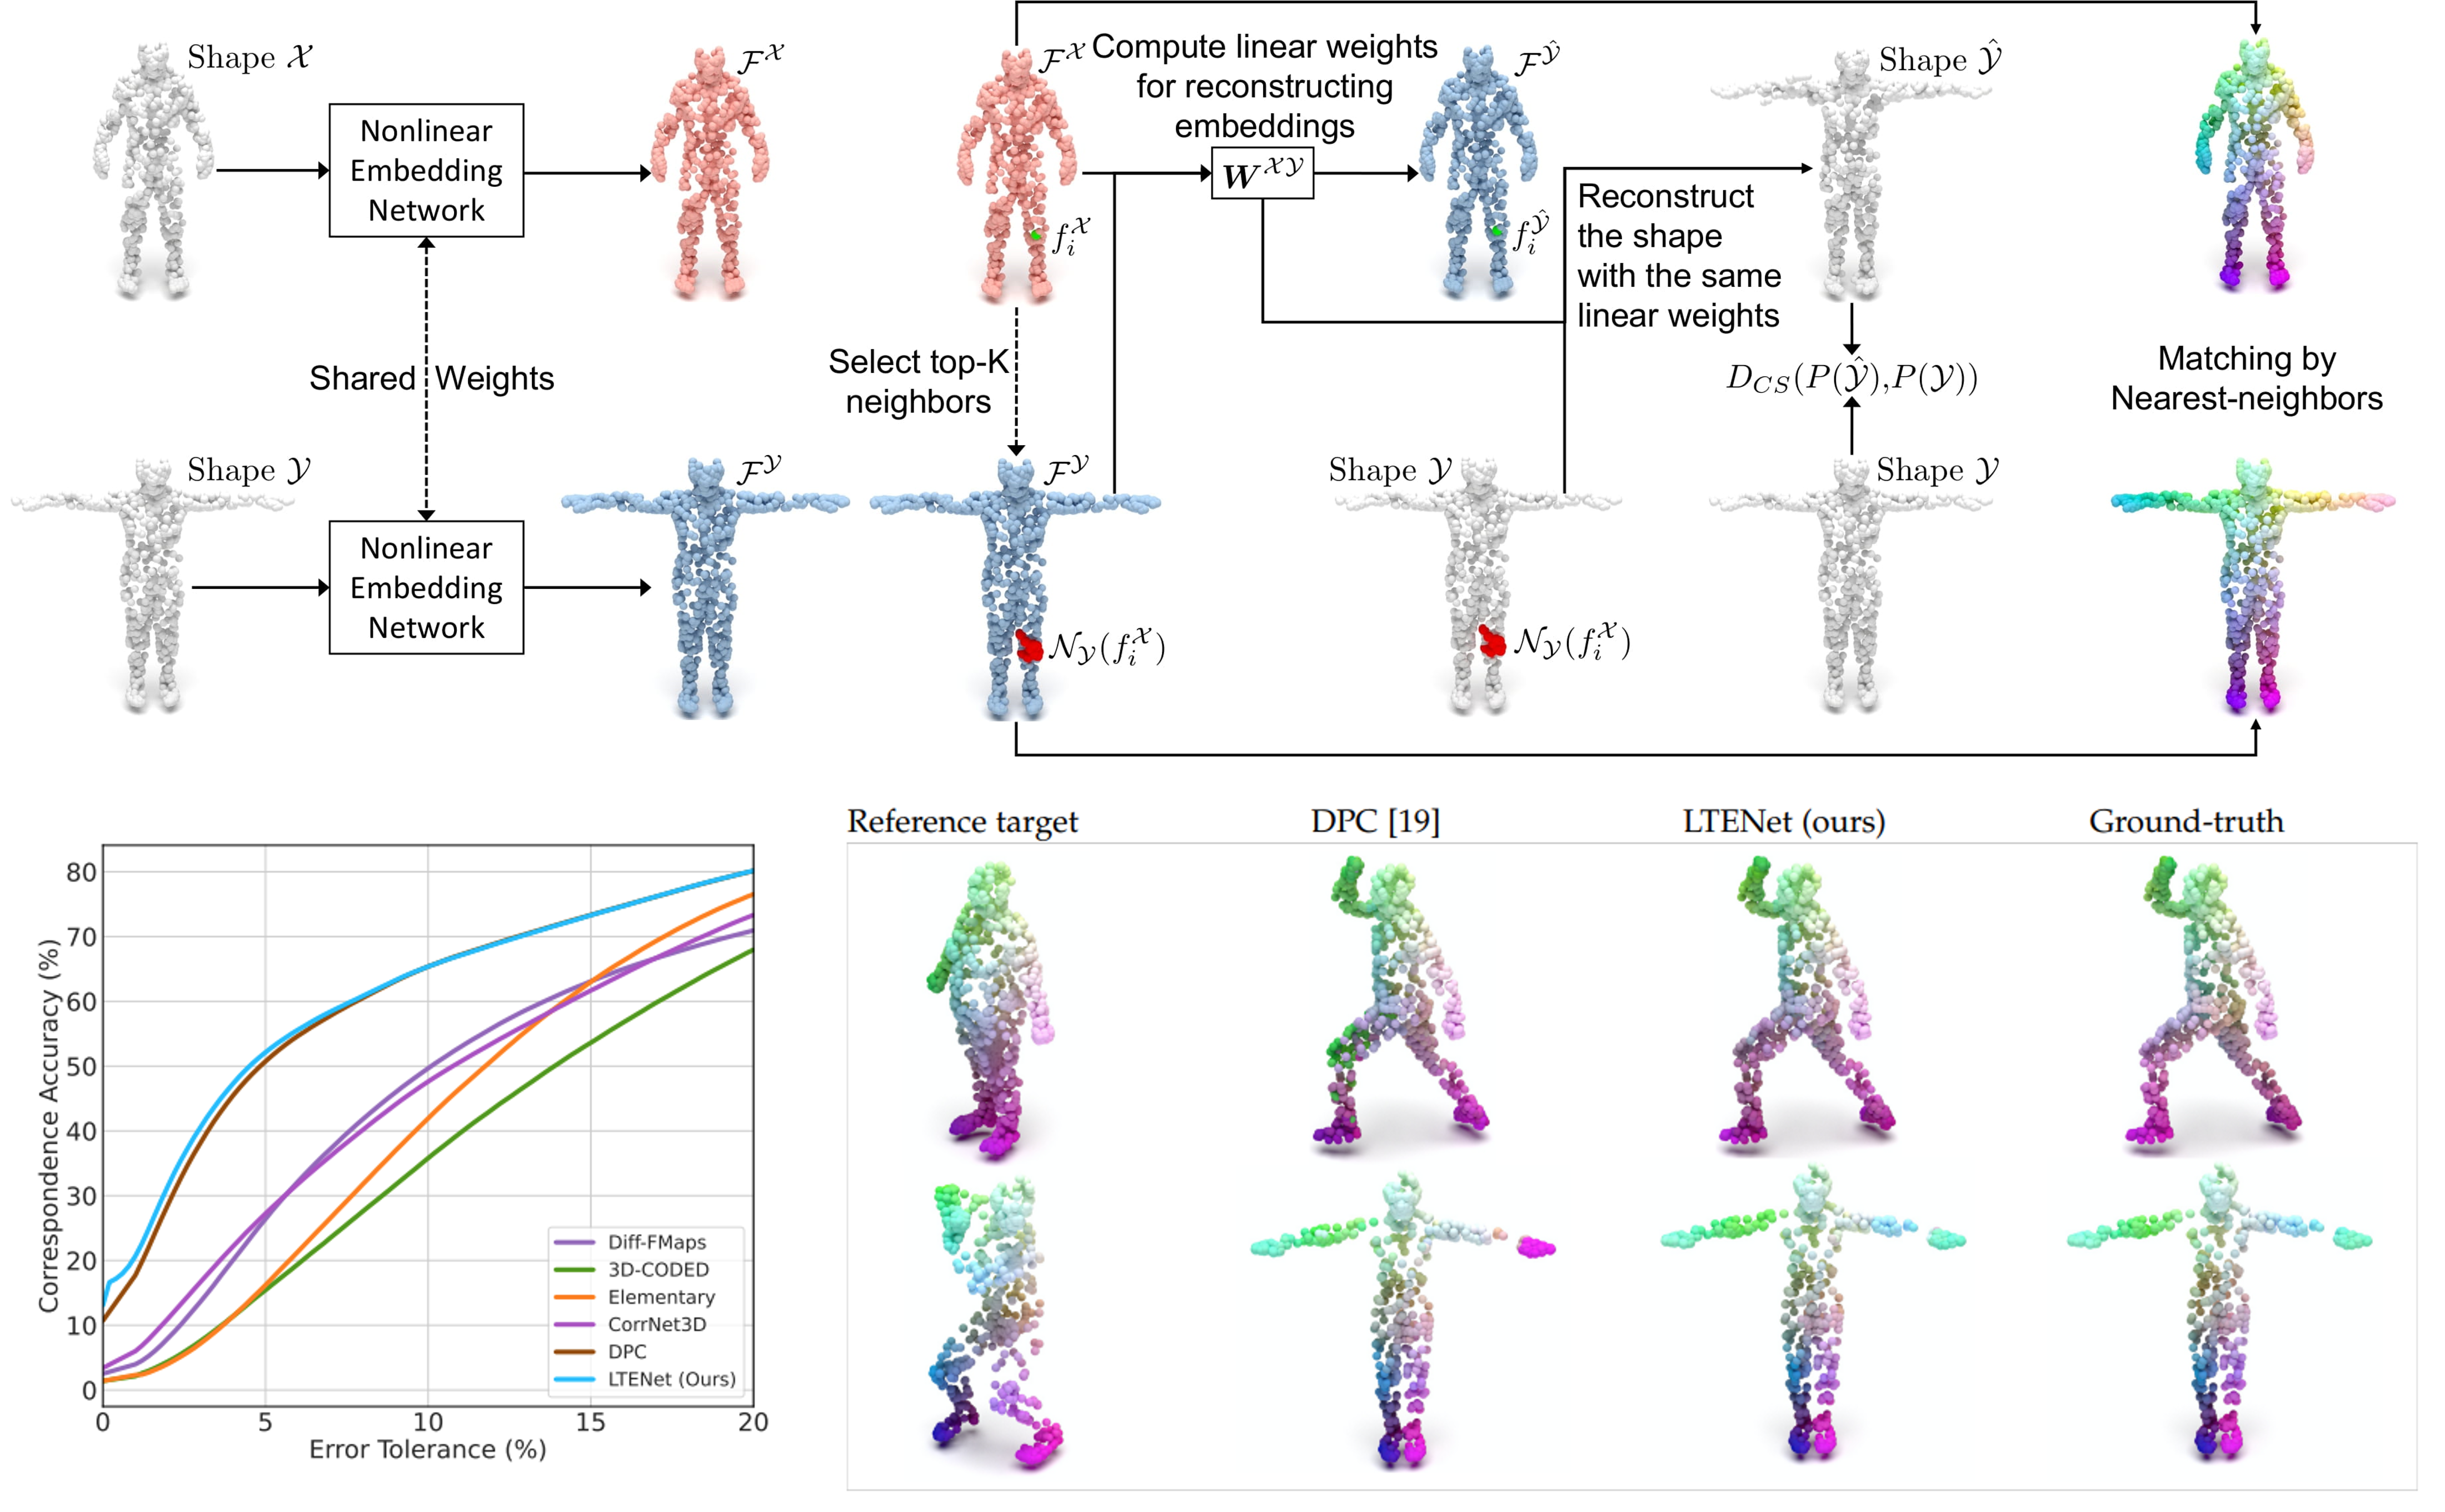
Learning Canonical Embeddings for Unsupervised Shape Correspondence with Locally Linear Transformations
IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI), 2023
We present a new approach to unsupervised shape correspondence learning between pairs of point clouds. We make the first attempt to adapt the classical locally linear embedding algorithm (LLE)—originally designed for nonlinear dimensionality reduction—for shape correspondence. The key idea is to find dense correspondences between shapes by first obtaining high-dimensional neighborhood-preserving embeddings of low-dimensional point clouds and subsequently aligning the source and target embeddings using locally linear transformations. We demonstrate that learning the embedding using a new LLE-inspired point cloud reconstruction objective results in accurate shape correspondences. More specifically, the approach comprises an end-to-end learnable framework of extracting high-dimensional neighborhood-preserving embeddings, estimating locally linear transformations in the embedding space, and reconstructing shapes via divergence measure-based alignment of probabilistic density functions built over reconstructed and target shapes. Our approach enforces embeddings of shapes in correspondence to lie in the same universal/canonical embedding space, which eventually helps regularize the learning process and leads to a simple nearest neighbors approach between shape embeddings for finding reliable correspondences. Comprehensive experiments show that the new method makes noticeable improvements over state-of-the-art approaches on standard shape correspondence benchmark datasets covering both human and nonhuman shapes.
@article{he2022learning, title={Learning Canonical Embeddings for Unsupervised Shape Correspondence with Locally Linear Transformations}, author={He, Pan and Emami, Patrick and Ranka, Sanjay and Rangarajan, Anand}, journal={IEEE Transactions on Pattern Analysis and Machine Intelligence (TPAMI)}, year={2022}, }, -
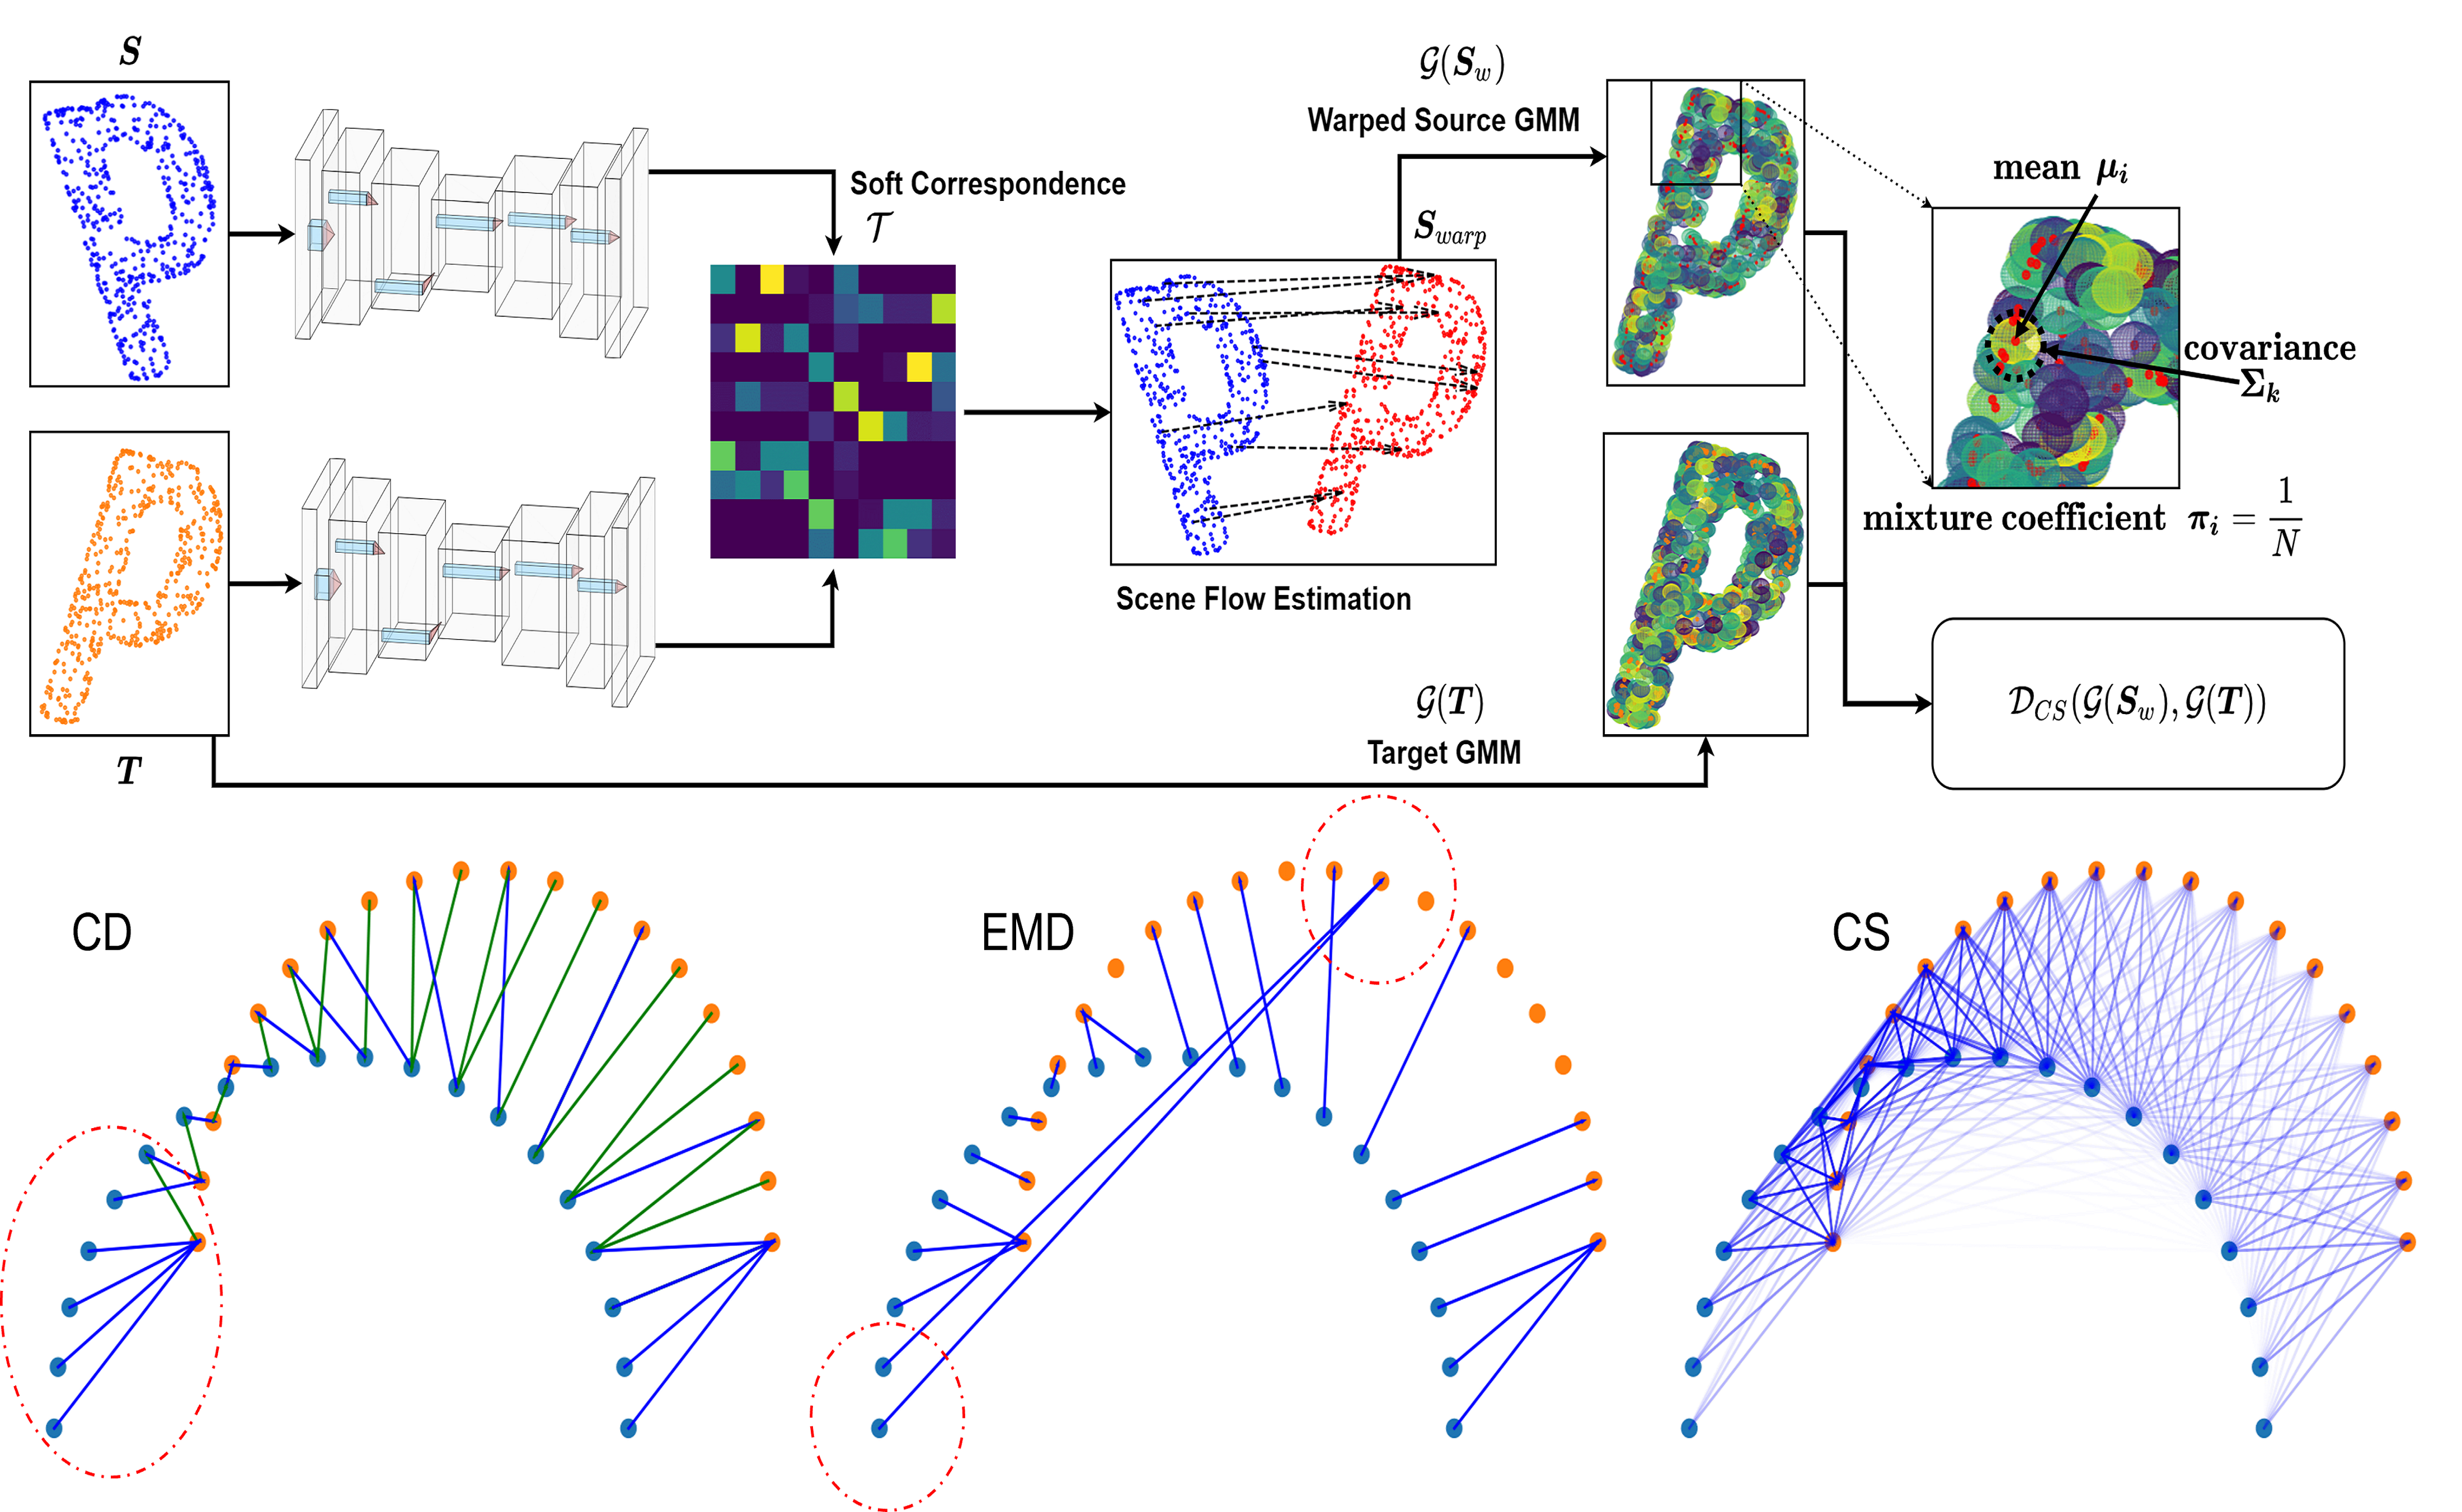
Self-Supervised Robust Scene Flow Estimation via the Alignment of Probability Density Functions
AAAI Conference on Artificial Intelligence (AAAI), 2022
In this paper, we present a new self-supervised scene flow estimation approach for a pair of consecutive point clouds. The key idea of our approach is to represent discrete point clouds as continuous probability density functions using Gaussian mixture models. Scene flow estimation is therefore converted into the problem of recovering motion from the alignment of probability density functions, which we achieve using a closed-form expression of the classic Cauchy-Schwarz divergence. Unlike existing nearest-neighbor-based approaches that use hard pairwise correspondences, our proposed approach establishes soft and implicit point correspondences between point clouds and generates more robust and accurate scene flow in the presence of missing correspondences and outliers. Comprehensive experiments show that our method makes noticeable gains over the Chamfer Distance and the Earth Mover’s Distance in real-world environments and achieves state-of-the-art performance among selfsupervised learning methods on FlyingThings3D and KITTI, even outperforming some supervised methods with ground truth annotations
@article{he2022self, title={Self-Supervised Robust Scene Flow Estimation via the Alignment of Probability Density Functions}, author={He, Pan and Emami, Patrick and Ranka, Sanjay and Rangarajan, Anand}, journal={AAAI Conference on Artificial Intelligence (AAAI)}, year={2022} } -
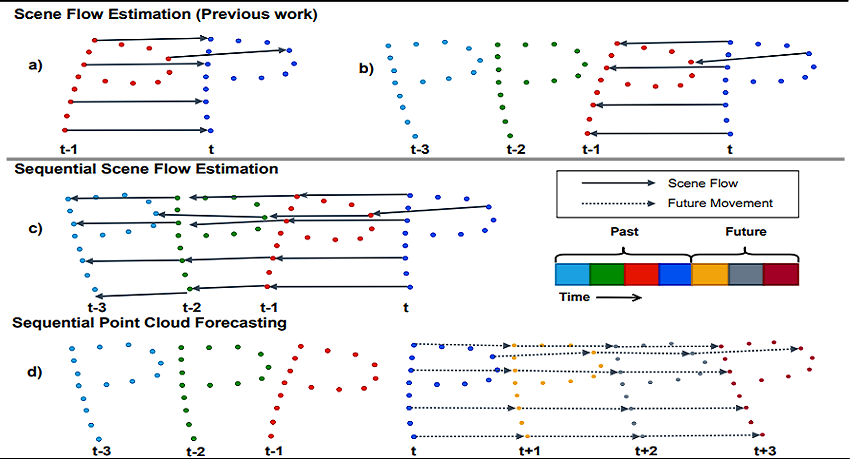
Learning Scene Dynamics from Point Cloud Sequences
International Journal of Computer Vision (IJCV), 2021 Special Issue on 3D Computer Vision
Understanding 3D scenes is a critical prerequisite for autonomous agents. Recently, LiDAR and other sensors have made large amounts of data available in the form of temporal sequences of point cloud frames. In this work, we propose a novel problem ---sequential scene flow estimation (SSFE)--- that aims to predict 3D scene flow for all pairs of point clouds in a given sequence. This is unlike the previously studied problem of scene flow estimation which focuses on two frames. We introduce the SPCM-Net architecture, which solves this problem by computing multi-scale spatiotemporal correlations between neighboring point clouds and then aggregating the correlation across time with an order-invariant recurrent unit. Our experimental evaluation confirms that recurrent processing of point cloud sequences results in significantly better SSFE compared to using only two frames. Additionally, we demonstrate that this approach can be effectively modified for sequential point cloud forecasting (SPF), a related problem that demands forecasting future point cloud frames. Our experimental results are evaluated using a new benchmark for both SSFE and SPF consisting of synthetic and real datasets. Previously, datasets for scene flow estimation have been limited to two frames. We provide non-trivial extensions to these datasets for multi-frame estimation and prediction. Due to the difficulty of obtaining ground truth motion for real-world datasets, we use self-supervised training and evaluation metrics. We believe that this benchmark will be pivotal to future research in this area. All code for benchmark and models will be made accessible at (https://github.com/BestSonny/SPCM).
@article{he2021learning, title={Learning Scene Dynamics from Point Cloud Sequences}, author={He, Pan and Emami, Patrick and Ranka, Sanjay and Rangarajan, Anand}, journal={International Journal of Computer Vision (IJCV)}, year={2021} } -
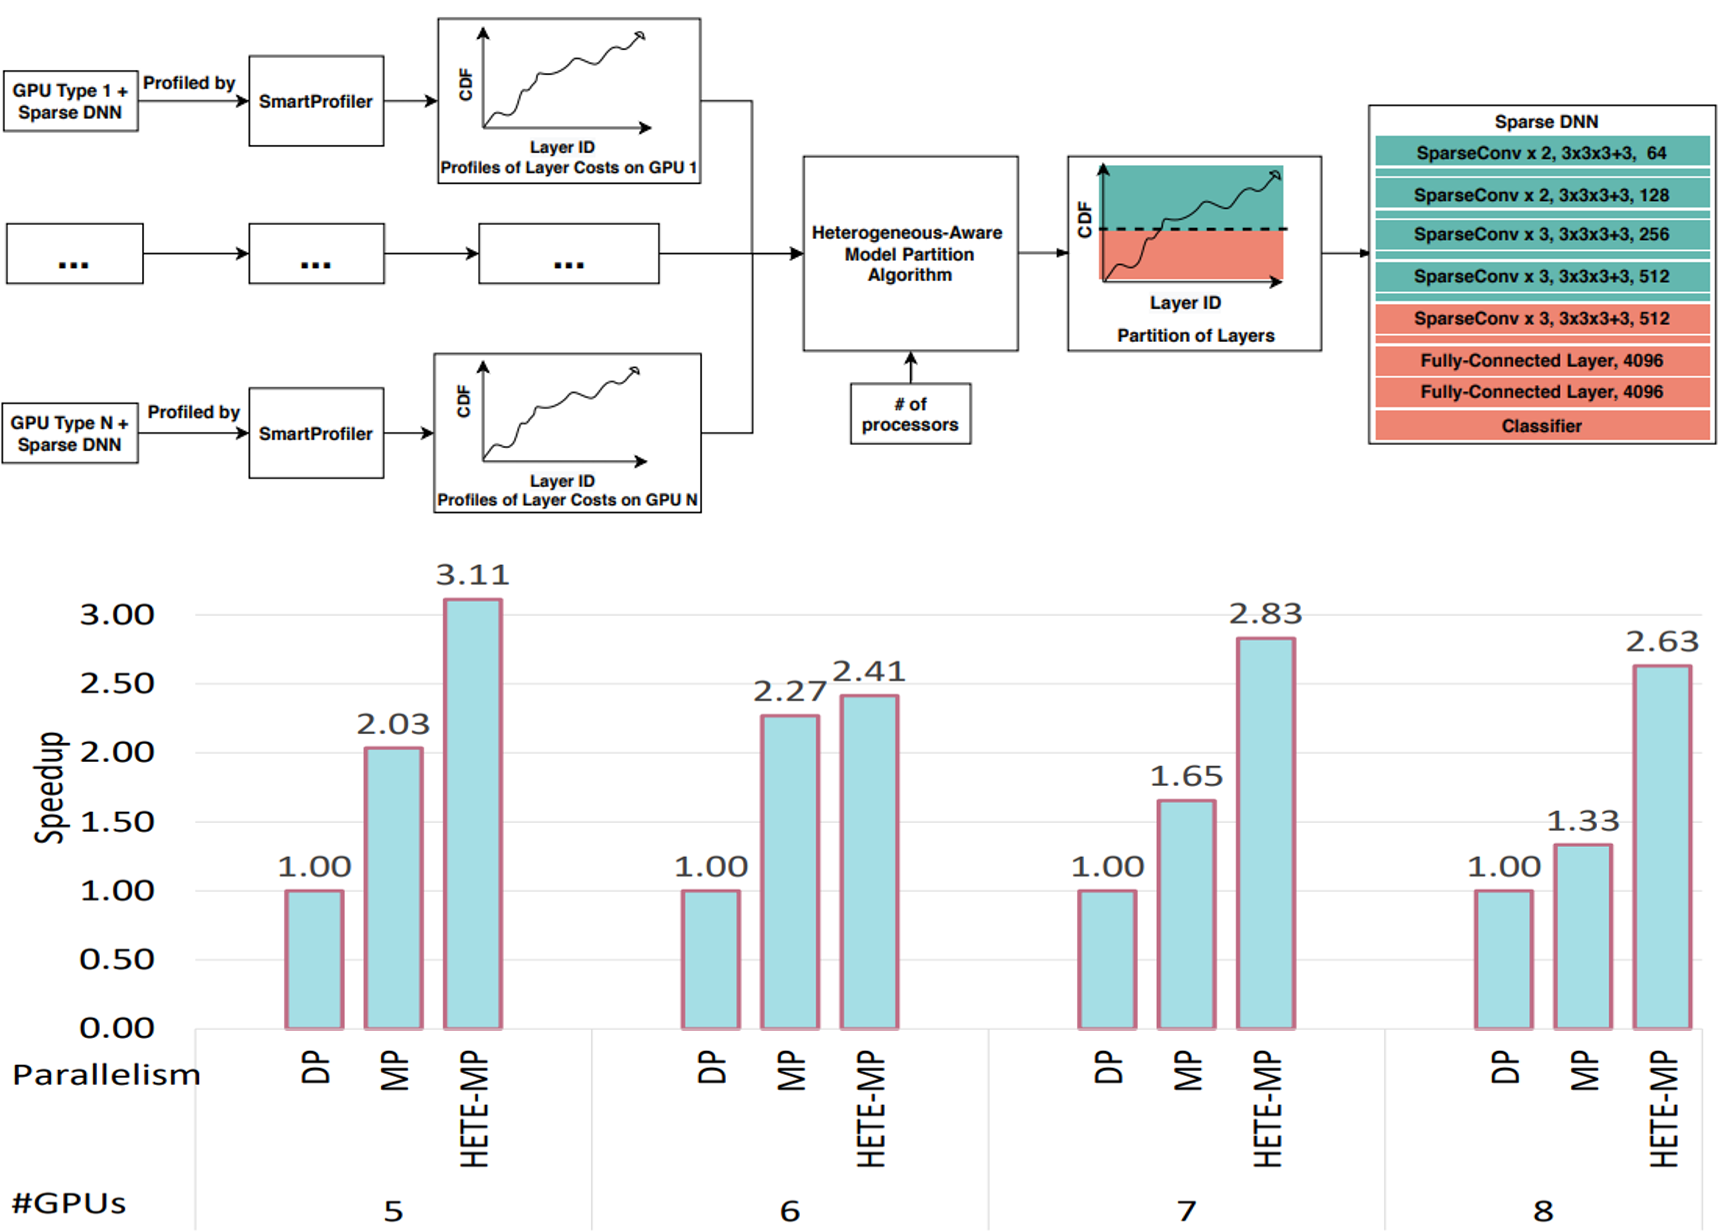
SparsePipe: Parallel Deep Learning for 3D Point Clouds
IEEE International Conference on High Performance Computing, Data, and Analytics (HiPC), 2020
We propose SparsePipe, an efficient and asynchronous parallelism approach for handling 3D point clouds with multi-GPU training. SparsePipe is built to support 3D sparse data such as point clouds. It achieves this by adopting generalized convolutions with sparse tensor representation to build expressive high-dimensional convolutional neural networks. Compared to dense solutions, the new models can efficiently process irregular point clouds without densely sliding over the entire space, significantly reducing the memory requirements and allowing higher resolutions of the underlying 3D volumes for better performance. SparsePipe exploits intra-batch parallelism that partitions input data into multiple processors and further improves the training throughput with inter-batch pipelining to overlap communication and computing. Besides, it suitably partitions the model when the GPUs are heterogeneous such that the computing is load-balanced with reduced communication overhead. Using experimental results on an eight-GPU platform, we show that SparsePipe can parallelize effectively and obtain better performance on current point cloud benchmarks for both training and inference, compared to its dense solutions.
@article{zhai2020sparsepipe, title={SparsePipe: Parallel Deep Learning for 3D Point Clouds}, author={Zhai, Keke and He, Pan and Banerjee, Tania and Rangarajan, Anand and Ranka, Sanjay}, journal={IEEE International Conference on High Performance Computing, Data, and Analytics (HiPC)}, year={2020} }
Object-Centric Learning
-
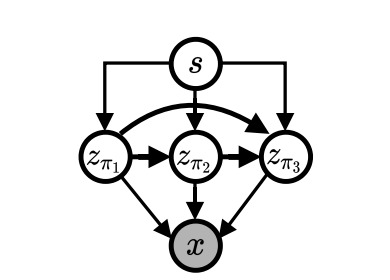
Towards Improving the Generation Quality of Autoregressive Slot VAEs
Neural Computation (Neural Comput.), Volume 36(5), 2024 · Accepted in 2023
Empowering agents with a compositional understanding of their environment is a promising next step toward solving long-horizon planning problems. On the one hand, we have seen encouraging progress on variational inference algorithms for obtaining sets of object-centric latent representations (“slots”) from unstructured scene observations. On the other hand, generating scenes from slots has received less attention, in part because it is complicated by the lack of a canonical object order. A canonical object order is useful for learning the object correlations necessary to generate physically plausible scenes similar to how raster scan order facilitates learning pixel correlations for pixel-level autoregressive image generation. In this work, we address this lack by learning a fixed object order for a hierarchical variational autoencoder with a single level of autoregressive slots and a global scene prior. We cast autoregressive slot inference as a set-to-sequence modeling problem. We introduce an auxiliary loss to train the slot prior to generate objects in a fixed order. During inference, we align a set of inferred slots to the object order obtained from a slot prior rollout. To ensure the rolled out objects are meaningful for the given scene, we condition the prior on an inferred global summary of the input. Experiments on compositional environments and ablations demonstrate that our model with global prior, inference with aligned slot order, and auxiliary loss achieves state-of-the-art sample quality.
@article{panhe-slot-vae-2024, title = {Towards Improving the Generation Quality of Autoregressive Slot VAEs}, author = {Patrick Emami and Pan He and Sanjay Ranka and Anand Rangarajan}, year = {2024}, journal = {Neural Computation (Neural Comput.)}, url = {https://direct.mit.edu/neco/article-abstract/36/5/858/119790} } -
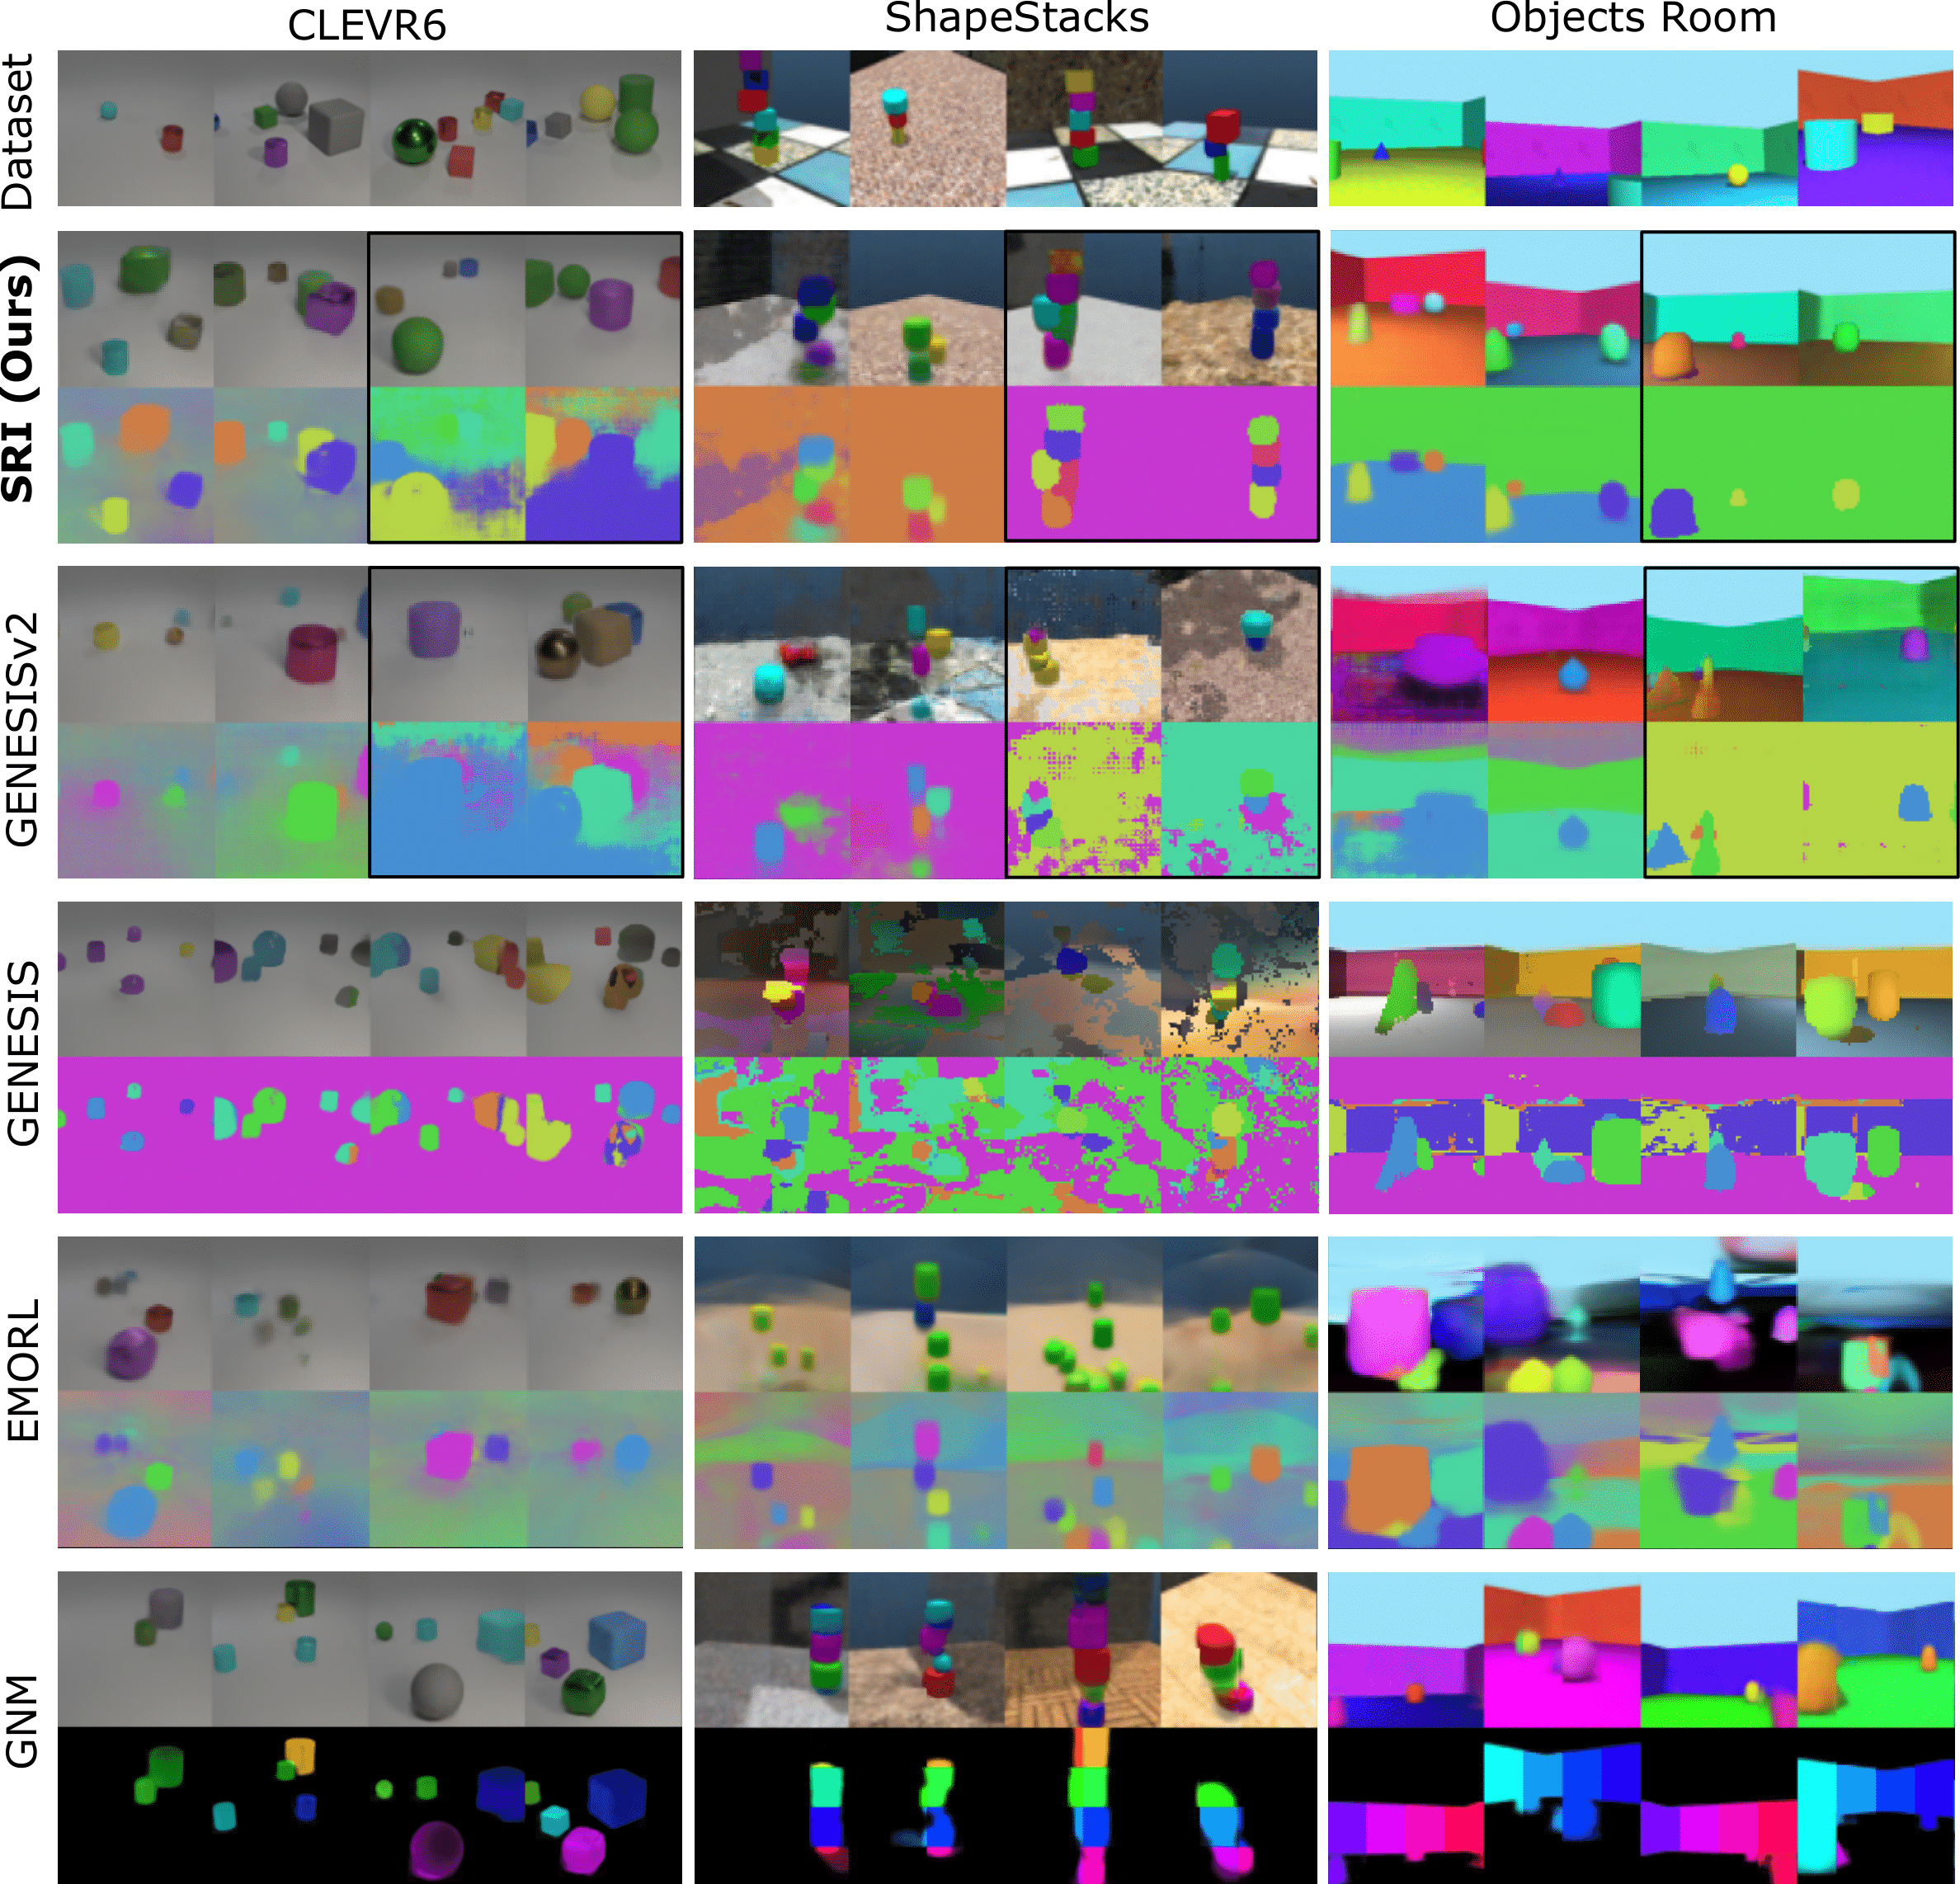
Slot Order Matters for Compositional Scene Understanding
arXiv preprint arXiv:2206.01370, 2022
Earlier preprint of Towards Improving the Generation Quality of Autoregressive Slot VAEs.
Empowering agents with a compositional understanding of their environment is a promising next step toward solving long-horizon planning problems. On the one hand, we have seen encouraging progress on variational inference algorithms for obtaining sets of object-centric latent representations (“slots”) from unstructured scene observations. On the other hand, generating scenes from slots has received less attention, in part because it is complicated by the lack of a canonical object order. A canonical object order is useful for learning the object correlations necessary to generate physically plausible scenes similar to how raster scan order facilitates learning pixel correlations for pixel-level autoregressive image generation. In this work, we address this lack by learning a fixed object order for a hierarchical variational autoencoder with a single level of autoregressive slots and a global scene prior. We cast autoregressive slot inference as a set-to-sequence modeling problem. We introduce an auxiliary loss to train the slot prior to generate objects in a fixed order. During inference, we align a set of inferred slots to the object order obtained from a slot prior rollout. To ensure the rolled out objects are meaningful for the given scene, we condition the prior on an inferred global summary of the input. Experiments on compositional environments and ablations demonstrate that our model with global prior, inference with aligned slot order, and auxiliary loss achieves state-of-the-art sample quality.
@misc{panhe-scholar-24, title = {{Slot Order Matters for Compositional Scene Understanding}}, author = {Patrick Emami and Pan He and Sanjay Ranka and Anand Rangarajan}, year = {2022}, note = {arXiv preprint arXiv:2206.01370, 2022}, url = {https://arxiv.org/abs/2206.01370v1} } -
Preview pending
Generating Scenes with Latent Object Models
Research manuscript, 2022
We introduce a structured latent variable model that learns the underlying data-generating process for a dataset of scenes. Our goals are to obtain a compositional scene representation and to perform scene generation by modeling statistical relationships between scenes as well as between objects within a scene. To make inference tractable, we take inspiration from visual topic models and introduce an interpretable hierarchy of scene-level and object-level latent variables (i.e., slots). Since generating scenes requires modeling dependencies between objects, we cannot make a bag-of-words assumption to simplify inference. Moreover, assuming that slots are generated with an autoregressive prior requires decomposing scenes sequentially during inference which has known limitations. Our approach is to assume that the assignment of objects to slots during generation is a deterministic function of the scene latent variable. This removes the need for sequential scene decomposition and enables us to propose an inference algorithm that uses orderless scene decomposition to indirectly estimate an ordered slot posterior. Qualitative and quantitative analysis establishes that our approach successfully learns a smoothly traversable scene-level latent space. The hierarchy of scene and slot variables improves the ability of slot-based models to generate samples displaying complex object relations. We also demonstrate that the learned hierarchy of representations can be used for a scene-retrieval application with object-centric re-ranking.
@misc{panhe-scholar-51, title = {{Generating Scenes with Latent Object Models}}, author = {Patrick Emami and Pan He and Sanjay Ranka and Anand Rangarajan}, year = {2022}, note = {Research manuscript}, url = {https://openreview.net/forum?id=WTXMNULQ3Uu} } -
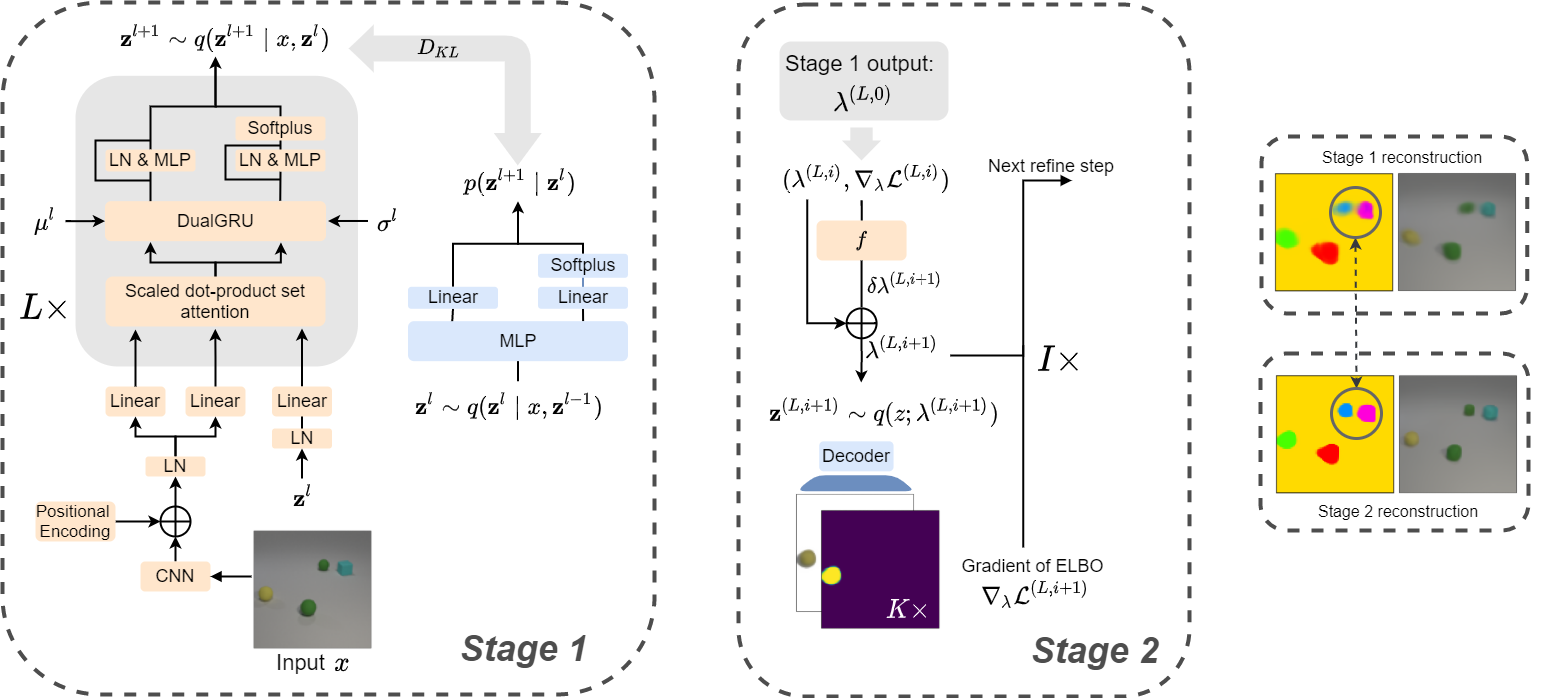
Efficient Iterative Amortized Inference for Learning Symmetric and Disentangled Multi-Object Representations
International Conference on Machine Learning (ICML), 2021
Unsupervised multi-object representation learning depends on inductive biases to guide the discovery of object-centric representations that generalize. However, we observe that methods for learning these representations are either impractical due to long training times and large memory consumption or forego key inductive biases. In this work, we introduce EfficientMORL, an efficient framework for the unsupervised learning of object-centric representations. We show that optimization challenges caused by requiring both symmetry and disentanglement can in fact be addressed by high-cost iterative amortized inference by designing the framework to minimize its dependence on it. We take a two-stage approach to inference: first, a hierarchical variational autoencoder extracts symmetric and disentangled representations through bottom-up inference, and second, a lightweight network refines the representations with top-down feedback. The number of refinement steps taken during training is reduced following a curriculum, so that at test time with zero steps the model achieves 99.1% of the refined decomposition performance. We demonstrate strong object decomposition and disentanglement on the standard multi-object benchmark while achieving nearly an order of magnitude faster training and test time inference over the previous state-of-the-art model.
@inproceedings{panhe-efficientmorl, title = {{Efficient Iterative Amortized Inference for Learning Symmetric and Disentangled Multi-Object Representations}}, author = {Patrick Emami and Pan He and Sanjay Ranka and Anand Rangarajan}, year = {2021}, booktitle = {International Conference on Machine Learning (ICML)}, url = {https://arxiv.org/pdf/2106.03630.pdf} } -
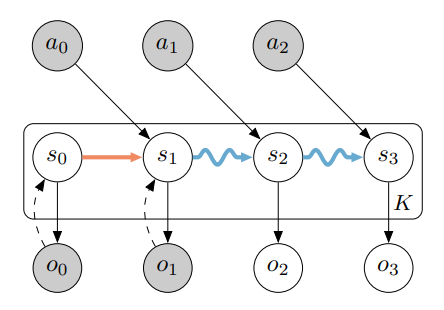
A Symmetric and Object-Centric World Model for Stochastic Environments
Workshop on Object Representations for Learning and Reasoning (ORLR) (Oral) and Workshop on Interpretable Inductive Biases and Physically Structured Learning (IBW) at the Conference on Neural Information Processing Systems (NeurIPS), 2020
Object-centric world models learn useful representations for planning and control but have so far only been applied to synthetic and deterministic environments. We introduce a perceptual-grouping-based world model for the dual task of extracting object-centric representations and modeling stochastic dynamics in visually complex and noisy video environments. The world model is built upon a novel latent state space model that learns the variance for object discovery and dynamics separately. This design is motivated by the disparity in available information that exists between the discovery component, which takes a provided video frame and decomposes it into objects, and the dynamics component, which predicts representations for future video frames conditioned only on past frames. To learn the dynamics variance, we introduce a best-of-many-rollouts objective. We show that the world model successfully learns accurate and diverse rollouts in a real-world robotic manipulation environment with noisy actions while learning interpretable object-centric representations.
@inproceedings{panhe-orlr,
  title = {{A Symmetric and Object-Centric World Model for Stochastic Environments}},
  author = {Patrick Emami and Pan He and Anand Rangarajan and Sanjay Ranka},
  year = {2020},
  booktitle = {Workshop on Object Representations for Learning and Reasoning (ORLR) (Oral) and Workshop on Interpretable Inductive Biases and Physically Structured Learning (IBW) at the Conference on Neural Information Processing Systems (NeurIPS)},
  url = {https://inductive-biases.github.io/papers/12.pdf}
}
Trustworthy AI & Security
-
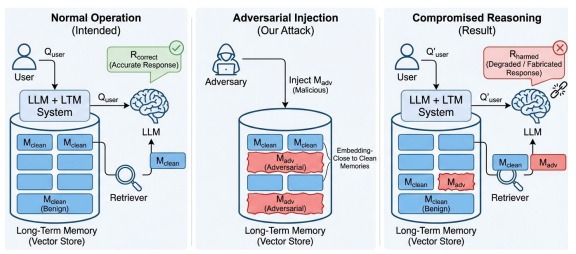
ER-MIA: Black-Box Adversarial Memory Injection Attacks on Long-Term Memory-Augmented Large Language Models
arXiv preprint, 2026
Large language models (LLMs) are increasingly augmented with long-term memory systems to overcome finite context windows and enable persistent reasoning across interactions. However, recent research finds that LLMs become more vulnerable because memory provides extra attack surfaces. In this paper, we present the first systematic study of black-box adversarial memory injection attacks that target the similarity-based retrieval mechanism in long-term memory-augmented LLMs. We introduce ER-MIA, a unified framework that exposes this vulnerability and formalizes two realistic attack settings: content-based attacks and question-targeted attacks. In these settings, ER-MIA includes an arsenal of composable attack primitives and ensemble attacks that achieve high success rates under minimal attacker assumptions. Extensive experiments across multiple LLMs and long-term memory systems demonstrate that similarity-based retrieval constitutes a fundamental and system-level vulnerability, revealing security risks that persist across memory designs and application scenarios.
@misc{panhe-er-mia-2026, title = {ER-MIA: Black-Box Adversarial Memory Injection Attacks on Long-Term Memory-Augmented Large Language Models}, author = {Mitchell Piehl and Zhaohan Xi and Zuobin Xiong and Pan He and Muchao Ye}, year = {2026}, note = {arXiv preprint, 2026}, url = {https://arxiv.org/abs/2602.15344} } -
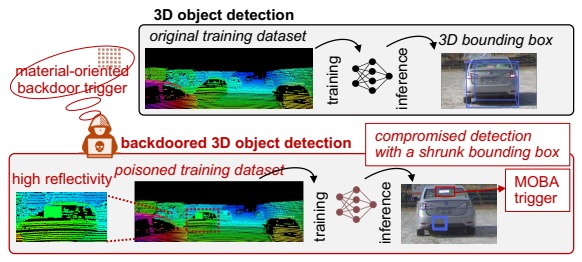
MOBA: A Material-Oriented Backdoor Attack against LiDAR-based 3D Object Detection Systems
AAAI Conference on Artificial Intelligence (AAAI), 2026 · First posted in 2025
Main technical track acceptance rate: 17.6%
@inproceedings{panhe-moba-2026, title = {MOBA: A Material-Oriented Backdoor Attack against LiDAR-based 3D Object Detection Systems}, author = {Saket Sanjeev Chaturvedi and Gaurav Bagwe and Lan Emily Zhang and Pan He and Xiaoyong Yuan}, year = {2026}, booktitle = {AAAI Conference on Artificial Intelligence (AAAI)}, url = {https://ojs.aaai.org/index.php/AAAI/article/view/40842} } -
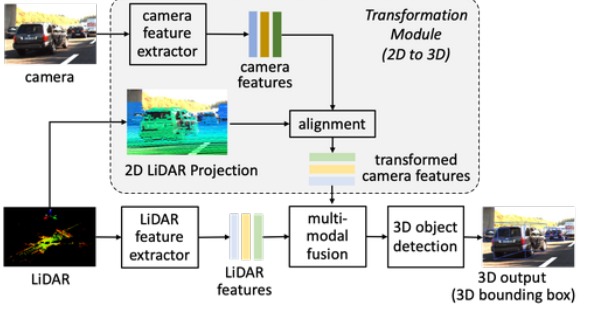
BadFusion: 2D-Oriented Backdoor Attacks against 3D Object Detection
International Joint Conference on Artificial Intelligence (IJCAI), 2024
3D object detection plays an important role in autonomous driving; however, its vulnerability to backdoor attacks has become evident. By injecting ''triggers'' to poison the training dataset, backdoor attacks manipulate the detector's prediction for inputs containing these triggers. Existing backdoor attacks against 3D object detection primarily poison 3D LiDAR signals, where large-sized 3D triggers are injected to ensure their visibility within the sparse 3D space, rendering them easy to detect and impractical in real-world scenarios. In this paper, we delve into the robustness of 3D object detection, exploring a new backdoor attack surface through 2D cameras. Given the prevalent adoption of camera and LiDAR signal fusion for high-fidelity 3D perception, we investigate the latent potential of camera signals to disrupt the process. Although the dense nature of camera signals enables the use of nearly imperceptible small-sized triggers to mislead 2D object detection, realizing 2D-oriented backdoor attacks against 3D object detection is non-trivial. The primary challenge emerges from the fusion process that transforms camera signals into a 3D space, compromising the association with the 2D trigger to the target output. To tackle this issue, we propose an innovative 2D-oriented backdoor attack against LiDAR-camera fusion methods for 3D object detection, named BadFusion, for preserving trigger effectiveness throughout the entire fusion process. The evaluation demonstrates the effectiveness of BadFusion, achieving a significantly higher attack success rate compared to existing 2D-oriented attacks.
@inproceedings{panhe-badfusion-2024, title = {BadFusion: 2D-Oriented Backdoor Attacks against 3D Object Detection}, author = {Saket Sanjeev Chaturvedi and Lan Zhang and Wenbin Zhang and Pan He and Xiaoyong Yuan}, year = {2024}, booktitle = {International Joint Conference on Artificial Intelligence (IJCAI)}, url = {https://arxiv.org/abs/2405.03884} } -
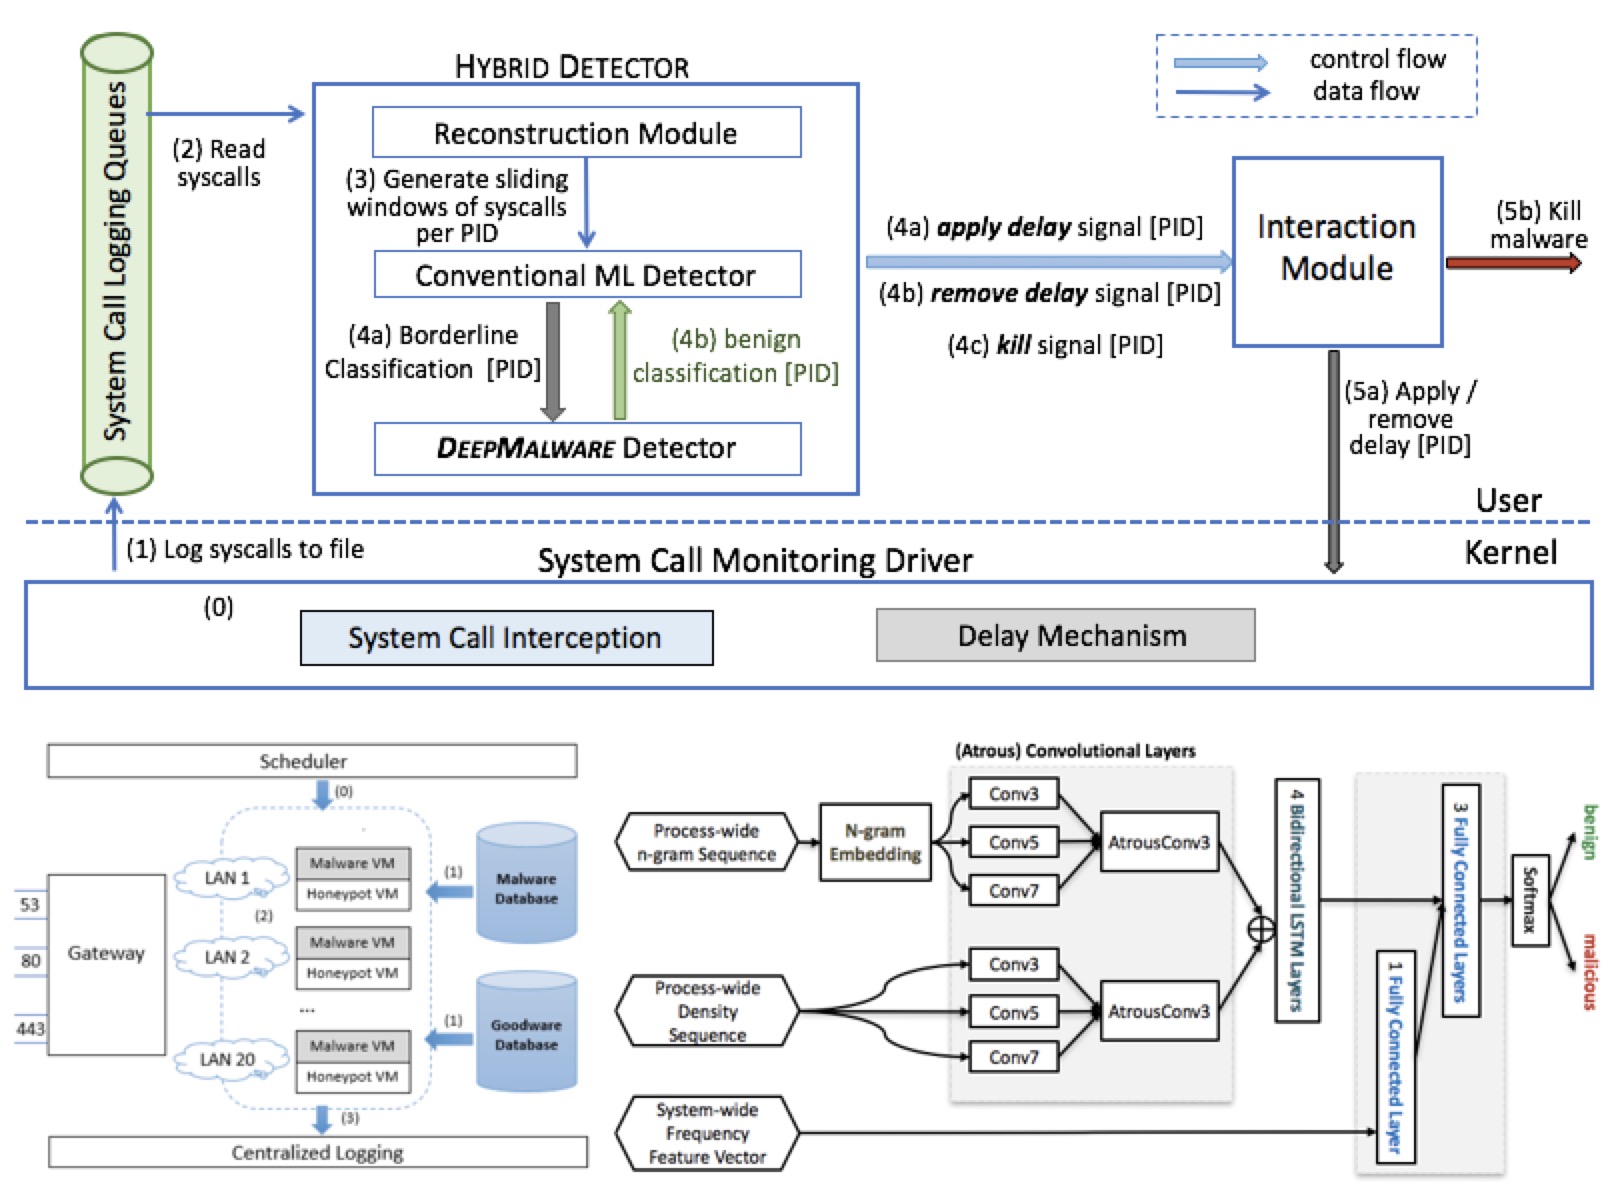
Learning Fast and Slow: PROPEDEUTICA for Real-time Malware Detection
IEEE Transactions on Neural Networks and Learning Systems (TNNLS), 2021
In this paper, we introduce and evaluate PROPEDEUTICA, a novel methodology and framework for efficient and effective real-time malware detection, leveraging the best of conventional machine learning (ML) and deep learning (DL) algorithms. In PROPEDEUTICA, all software processes in the system start execution subjected to a conventional ML detector for fast classification. If a piece of software receives a borderline classification, it is subjected to further analysis via more performance expensive and more accurate DL methods, via our newly proposed DL algorithm DEEPMALWARE. Further, in an exploratory fashion, we introduce delays to the execution of software subjected to DEEPMALWARE as a way to “buy time” for DL analysis and to rate-limit the impact of possible malware in the system. We evaluated PROPEDEUTICA with a set of 9,115 malware samples and 877 commonly used benign software samples from various categories for the Windows OS. Our results show that the false positive rate for conventional ML methods can reach 20%, and for modern DL methods it is usually below 6%. However, the classification time for DL can be 100X longer than conventional ML methods. PROPEDEUTICA improved the detection F1-score from 77.54% (conventional ML method) to 90.25% (16.39% increase), and reduced the detection time by 54.86%. Further, the percentage of software subjected to DL analysis was approximately 40% on average. Further, the application of delays in software subjected to ML reduced the detection time by approximately 10%. Finally, we found and discussed a discrepancy between the detection accuracy offline (analysis after all traces are collected) and on-the-fly (analysis in tandem with trace collection). Conventional ML experienced a decrease of 13% in accuracy when executed offline (89.05%) compared to online (77.54%) with the same traces. Our insights show that conventional ML and modern DLbased malware detectors in isolation cannot meet the needs of efficient and effective malware detection: high accuracy, low false positive rate, and short classification time.
@article{sun2017learning, title={Learning fast and slow: Propedeutica for real-time malware detection}, author={Sun, Ruimin and Yuan, Xiaoyong and He, Pan and Zhu, Qile and Chen, Aokun and Gregio, Andre and Oliveira, Daniela and Li, Xiaolin}, journal={IEEE Transactions on Neural Networks and Learning Systems (TNNLS)}, year={2017} } -

Adaptive Adversarial Attack on Scene Text Recognition
Eighth International Workshop on Security and Privacy in Big Data, in conjunction with the IEEE International Conference on Computer Communications (INFOCOM), 2020
Recent studies have shown that state-of-the-art deep learning models are vulnerable to the inputs with small perturbations (adversarial examples). We observe two critical obstacles in adversarial examples: (i) Recent adversarial attacks require manually tuning hyper-parameters and take a long time to construct an adversarial example, making it impractical to attack real-time systems; (ii) Most of the studies focus on nonsequential tasks, such as image classification, yet only a few consider sequential tasks. In this work, we propose an adaptive approach to speed up adversarial attacks, especially on sequential learning tasks. By leveraging the uncertainty of each task, we directly learn the adaptive multi-task weightings, without manually searching hyper-parameters. A unified architecture is developed and evaluated for both non-sequential tasks and sequential ones. To evaluate the effectiveness, we take the scene text recognition task as a case study. To our best knowledge, our proposed method is the first attempt to adversarial attack for scene text recognition. Adaptive Attack achieves over 99.9% success rate with 3 ∼ 6× speedup compared to state-of-the-art adversarial attacks.
@inproceedings{yuan2020adaptive, title={Adaptive adversarial attack on scene text recognition}, author={Yuan, Xiaoyong and He, Pan and Lit, Xiaolin and Wu, Dapeng}, booktitle={Eighth International Workshop on Security and Privacy in Big Data, in conjunction with the IEEE International Conference on Computer Communications (INFOCOM)}, pages={358--363}, year={2020}, organization={IEEE} } -
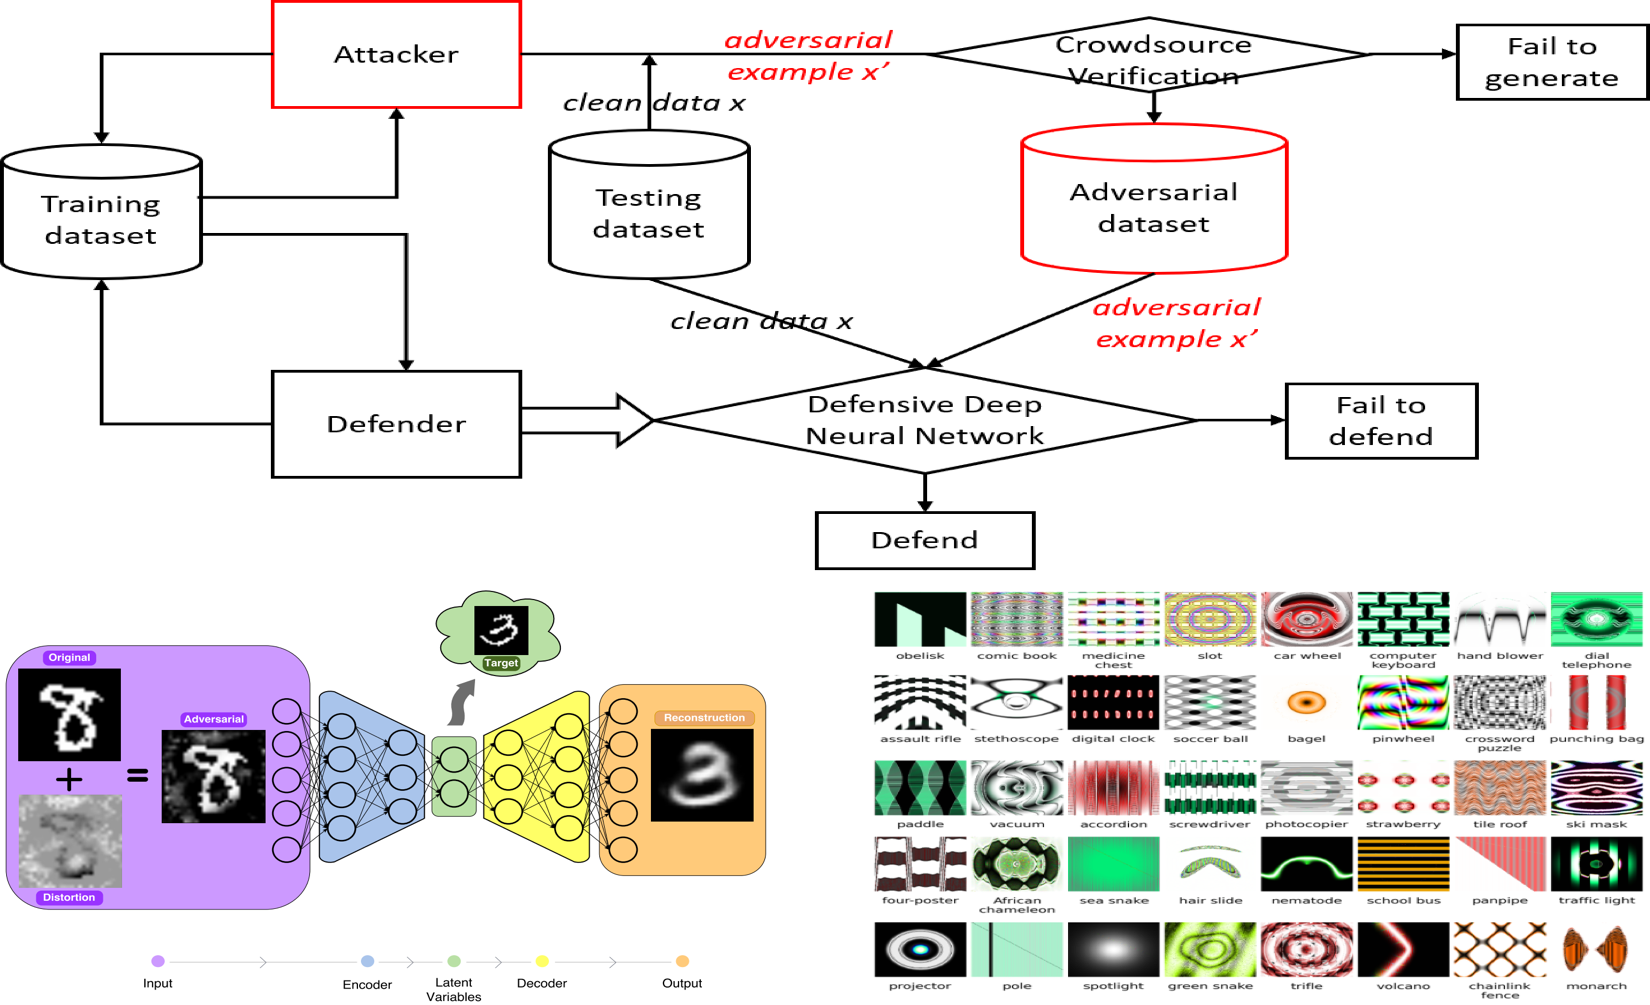
Adversarial Examples: Attacks and Defenses for Deep Learning
IEEE Transactions on Neural Networks and Learning Systems (TNNLS) · Scholar record: 2017
With rapid progress and significant successes in a wide spectrum of applications, deep learning is being applied in many safety-critical environments. However, deep neural networks (DNNs) have been recently found vulnerable to well-designed input samples called adversarial examples. Adversarial perturbations are imperceptible to human but can easily fool DNNs in the testing/deploying stage. The vulnerability to adversarial examples becomes one of the major risks for applying DNNs in safety-critical environments. Therefore, attacks and defenses on adversarial examples draw great attention. In this paper, we review recent findings on adversarial examples for DNNs, summarize the methods for generating adversarial examples, and propose a taxonomy of these methods. Under the taxonomy, applications for adversarial examples are investigated. We further elaborate on countermeasures for adversarial examples. In addition, three major challenges in adversarial examples and the potential solutions are discussed.
@article{yuan2019adversarial, title={Adversarial examples: Attacks and defenses for deep learning}, author={Yuan, Xiaoyong and He, Pan and Zhu, Qile and Li, Xiaolin}, journal={IEEE Transactions on Neural Networks and Learning Systems (TNNLS)}, volume={30}, number={9}, pages={2805--2824}, year={2019}, publisher={IEEE} }
Scene Text and Scene Understanding
-
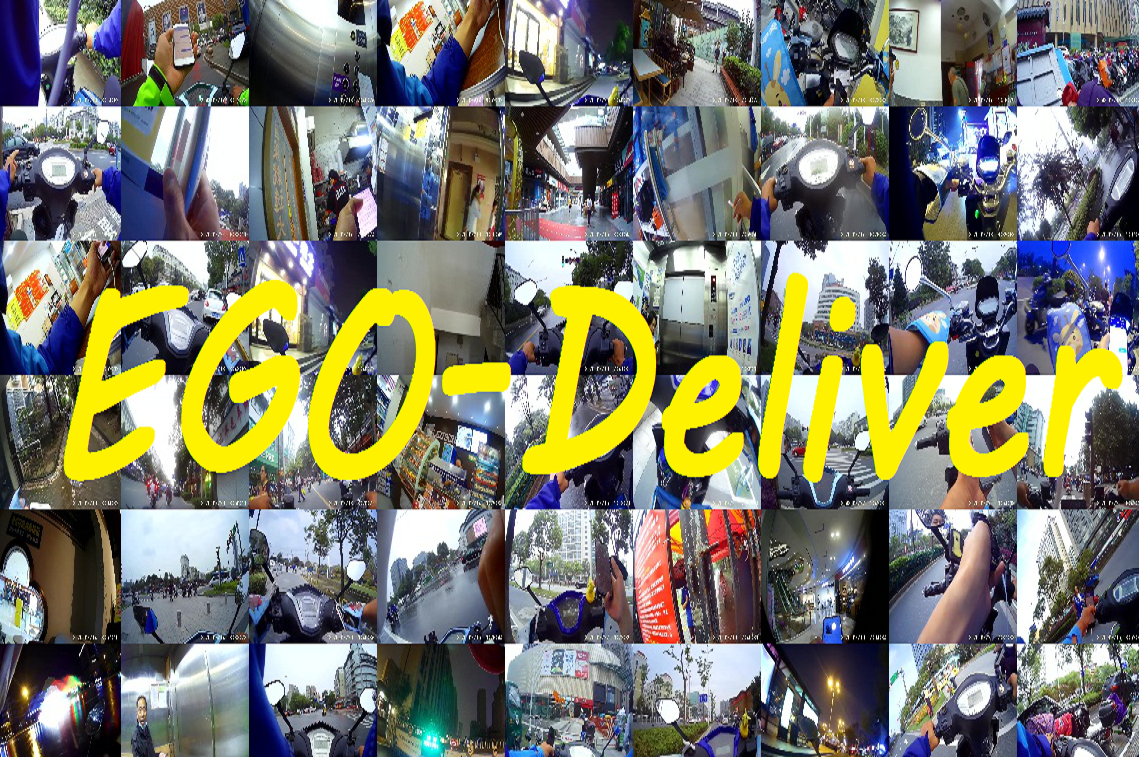
Ego-Deliver: A Large-Scale Dataset for Egocentric Video Analysis
ACM International Conference on Multimedia (ACM-MM), 2021
The egocentric video provides a unique view of event participants to show their attention, vision, and interaction with objects. In this paper, we introduce Ego-Deliver, a new large-scale egocentric video benchmark recorded by takeaway riders about their daily work. To the best of our knowledge, Ego-Deliver presents the first attempt in understanding activities from the takeaway delivery process while being one of the largest egocentric video action datasets to date. Our dataset provides a total of 5,360 videos with more than 139,000 multi-track annotations and 45 different attributes, which we believe is pivotal to future research in this area. We introduce the FS-Net architecture, a new anchor-free action detection approach handling extreme variations of action durations. We partition videos into fragments and build dynamic graphs over fragments, where multi-fragment context information is aggregated to boost fragment classification. A splicing and scoring module is applied to obtain final action proposals. Our experimental evaluation confirms that the proposed framework outperforms existing approaches on the proposed Ego-Deliver benchmark and is competitive on other popular benchmarks. In our current version, Ego-Deliver is used to make a comprehensive comparison between algorithms for activity detection. We also show its application to action recognition with promising results. The dataset, toolkits and baseline results will be made available at https://github.com/EgoDeliver/EgoDeliver_Dataset.
@inproceedings{qiu2021ego, title={Ego-Deliver: A Large-Scale Dataset for Egocentric Video Analysis}, author={Haonan Qiu, Pan He, Shuchun Liu, Weiyuan Shao, Feiyun Zhang, Jiajun Wang, Liang He, Feng Wang}, booktitle={ACM International Conference on Multimedia (ACM-MM)}, year={2021} } -
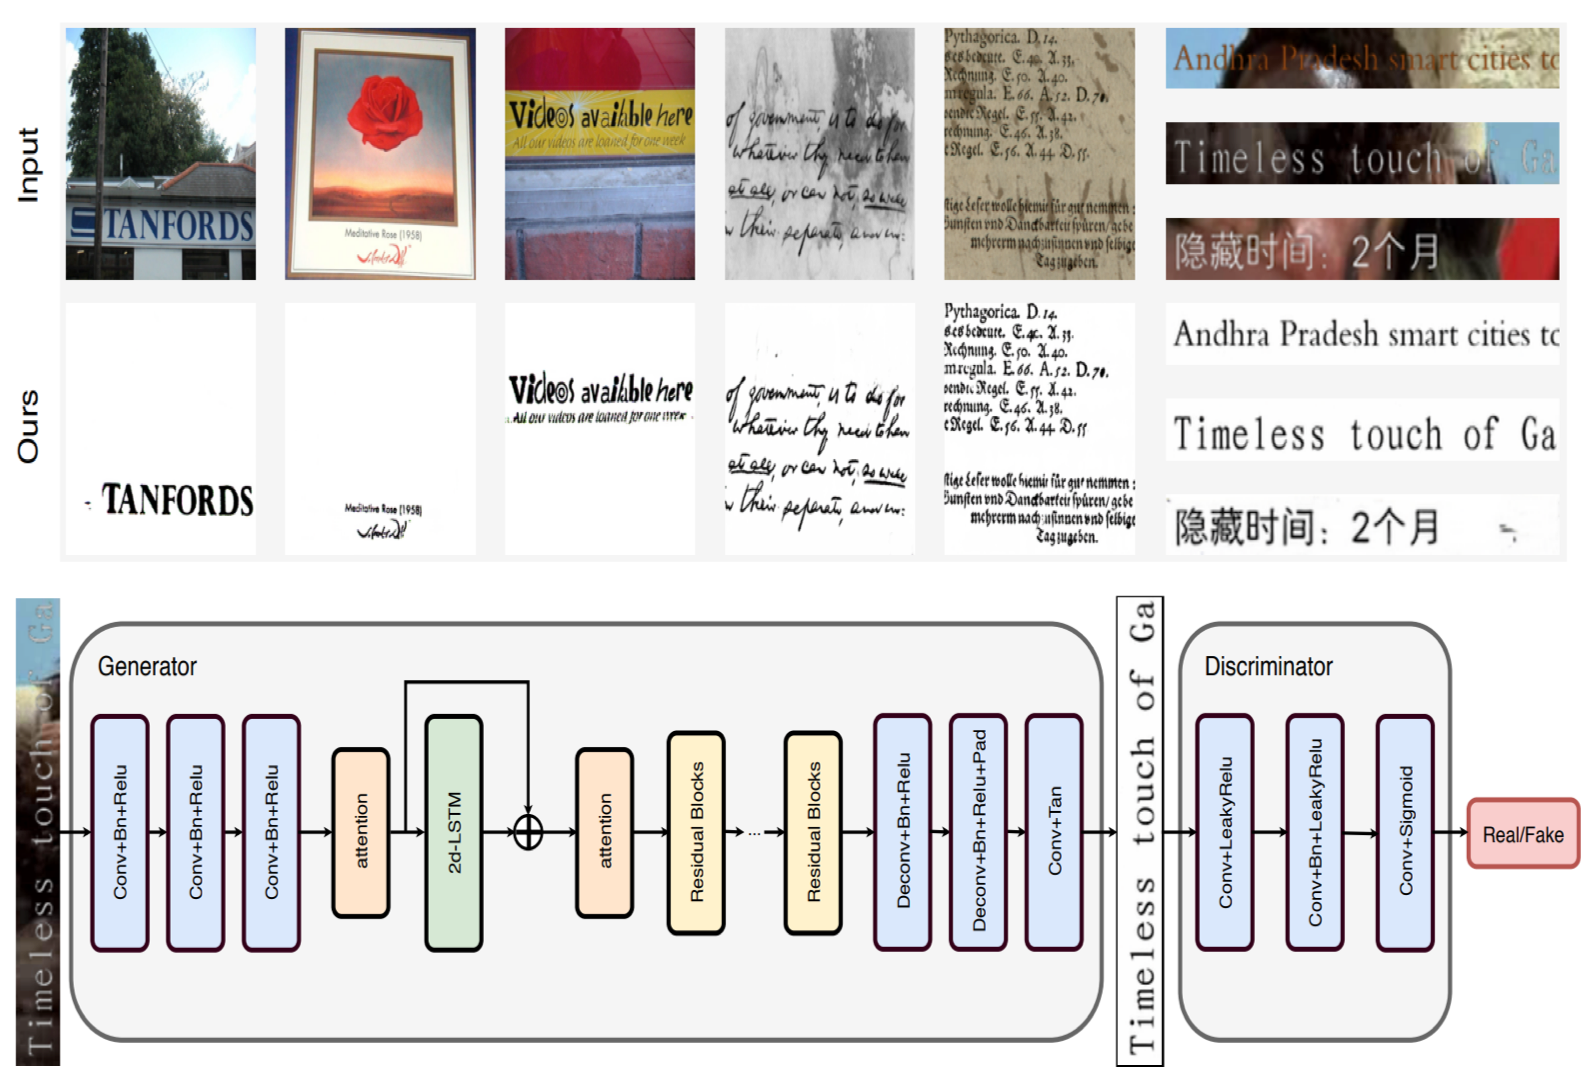
Document Binarization using Recurrent Attention Generative Model
British Machine Vision Conference (BMVC), 2019
We develop a general deep learning approach, by introducing a recurrent attention generative model with adversarial training to do image binarization which is an elementary pre-processing step in the document image analysis and recognition pipeline. The document binarization using recurrent attention generative(DB-RAM) model comprises three contributions: First, to suppress the interference from complex background, non-local attention blocks are incorporated to capture spatial long-range dependencies. Second, we explore the use of Spatial Recurrent Neural Networks (SRNNs) to pass spatially varying contextual information across an image, which leverages the prior knowledge of text orientation and semantics. Third, to validate the effectiveness of our proposed method, we further synthetically generate two comprehensive subtitle datasets that cover various real-world conditions. Evaluated on various standard benchmarks, our proposed method significantly outperforms state-of-the-art binarization methods both quantitatively and qualitatively. The supplementary material also shows that the proposed method improves the recognition rate and also performs well in the task of image unshadowing, which evidently verifies its generality
@inproceedings{liu2019document, title={Document Binarization using Recurrent Attention Generative Model}, author={Liu, Shuchun and Zhang, Feiyun and Chen, MingXi and Xie, YuFei and He, Pan and Shao, Jie}, booktitle={British Machine Vision Conference (BMVC)}, pages={95}, year={2019} } -

Boosting up Scene Text Detectors with Guided CNN
British Machine Vision Conference (BMVC), 2018 · Oral presentation
Acceptance rate: 29.5% · Oral acceptance rate: 4.29%
Deep CNNs have achieved great success in text detection. Most of existing methods attempt to improve accuracy with sophisticated network design, while paying less attention on speed. In this paper, we propose a general framework for text detection called Guided CNN to achieve the two goals simultaneously. The proposed model consists of one guidance subnetwork, where a guidance mask is learned from the input image itself, and one primary text detector, where every convolution and non-linear operation are conducted only in the guidance mask. On the one hand, the guidance subnetwork filters out non-text regions coarsely, greatly reduces the computation complexity. On the other hand, the primary text detector focuses on distinguishing between text and hard nontext regions and regressing text bounding boxes, achieves a better detection accuracy. A training strategy, called background-aware block-wise random synthesis, is proposed to further boost up the performance. We demonstrate that the proposed Guided CNN is not only effective but also efficient with two state-of-the-art methods, CTPN [52] and EAST [64], as backbones. On the challenging benchmark ICDAR 2013, it speeds up CTPN by 2.9 times on average, while improving the F-measure by 1.5%. On ICDAR 2015, it speeds up EAST by 2.0 times while improving the F-measure by 1.0%.
@inproceedings{YueKZCH0Z18, author={Xiaoyu Yue and Zhanghui Kuang and Zhaoyang Zhang and Zhenfang Chen and Pan He and Yu Qiao and Wei Zhang}, title={Boosting up Scene Text Detectors with Guided CNN}, year={2018}, pages={307}, booktitle={British Machine Vision Conference (BMVC)}, } -
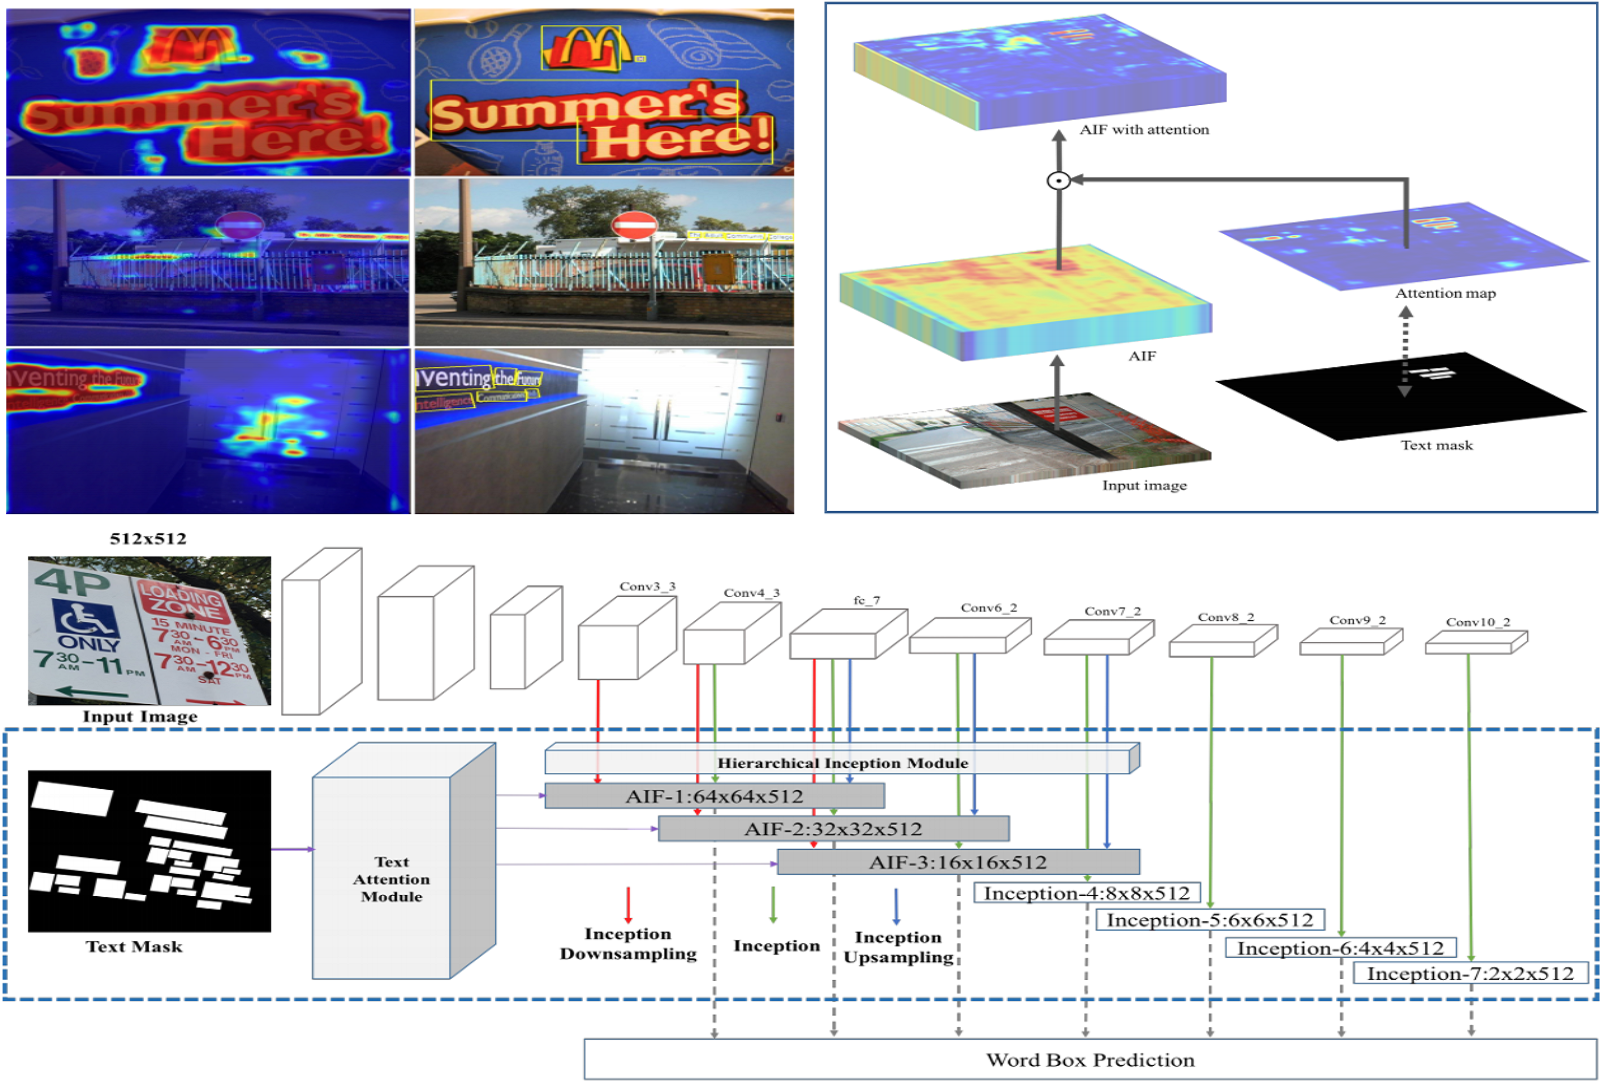
Single Shot Text Detector with Regional Attention
IEEE International Conference on Computer Vision (ICCV), 2017 · Spotlight presentation
Acceptance rate: 29.0% · Spotlight acceptance rate: 2.61%
We present a novel single-shot text detector that directly outputs word-level bounding boxes in a natural image. We propose an attention mechanism which roughly identifies text regions via an automatically learned attentional map. This substantially suppresses background interference in the convolutional features, which is the key to producing accurate inference of words, particularly at extremely small sizes. This results in a single model that essentially works in a coarse-to-fine manner. It departs from recent FCNbased text detectors which cascade multiple FCN models to achieve an accurate prediction. Furthermore, we develop a hierarchical inception module which efficiently aggregates multi-scale inception features. This enhances local details, and also encodes strong context information, allowing the detector to work reliably on multi-scale and multiorientation text with single-scale images. Our text detector achieves an F-measure of 77% on the ICDAR 2015 benchmark, advancing the state-of-the-art results
@inproceedings{he2017single, title={Single shot text detector with regional attention}, author={He, Pan and Huang, Weilin and He, Tong and Zhu, Qile and Qiao, Yu and Li, Xiaolin}, booktitle={IEEE International Conference on Computer Vision (ICCV)}, pages={3047--3055}, year={2017} } -
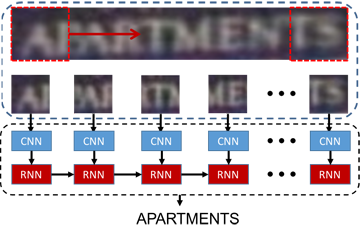
Reading Scene Text in Deep Convolutional Sequences
The 30th AAAI Conference on Artificial Intelligence (AAAI), 2016 (Oral)
We develop a Deep-Text Recurrent Network (DTRN) that regards scene text reading as a sequence labelling problem. We leverage recent advances of deep convolutional neural networks to generate an ordered highlevel sequence from a whole word image, avoiding the difficult character segmentation problem. Then a deep recurrent model, building on long short-term memory (LSTM), is developed to robustly recognize the generated CNN sequences, departing from most existing approaches recognising each character independently. Our model has a number of appealing properties in comparison to existing scene text recognition methods: (i) It can recognise highly ambiguous words by leveraging meaningful context information, allowing it to work reliably without either pre- or post-processing; (ii) the deep CNN feature is robust to various image distortions; (iii) it retains the explicit order information in word image, which is essential to discriminate word strings; (iv) the model does not depend on pre-defined dictionary, and it can process unknown words and arbitrary strings. It achieves impressive results on several benchmarks, advancing the-state-of-the-art substantially
@inproceedings{he2016reading, title={Reading scene text in deep convolutional sequences}, author={He, Pan and Huang, Weilin and Qiao, Yu and Loy, Chen and Tang, Xiaoou}, booktitle={The 30th AAAI Conference on Artificial Intelligence (AAAI)}, volume={30}, number={1}, year={2016} } -
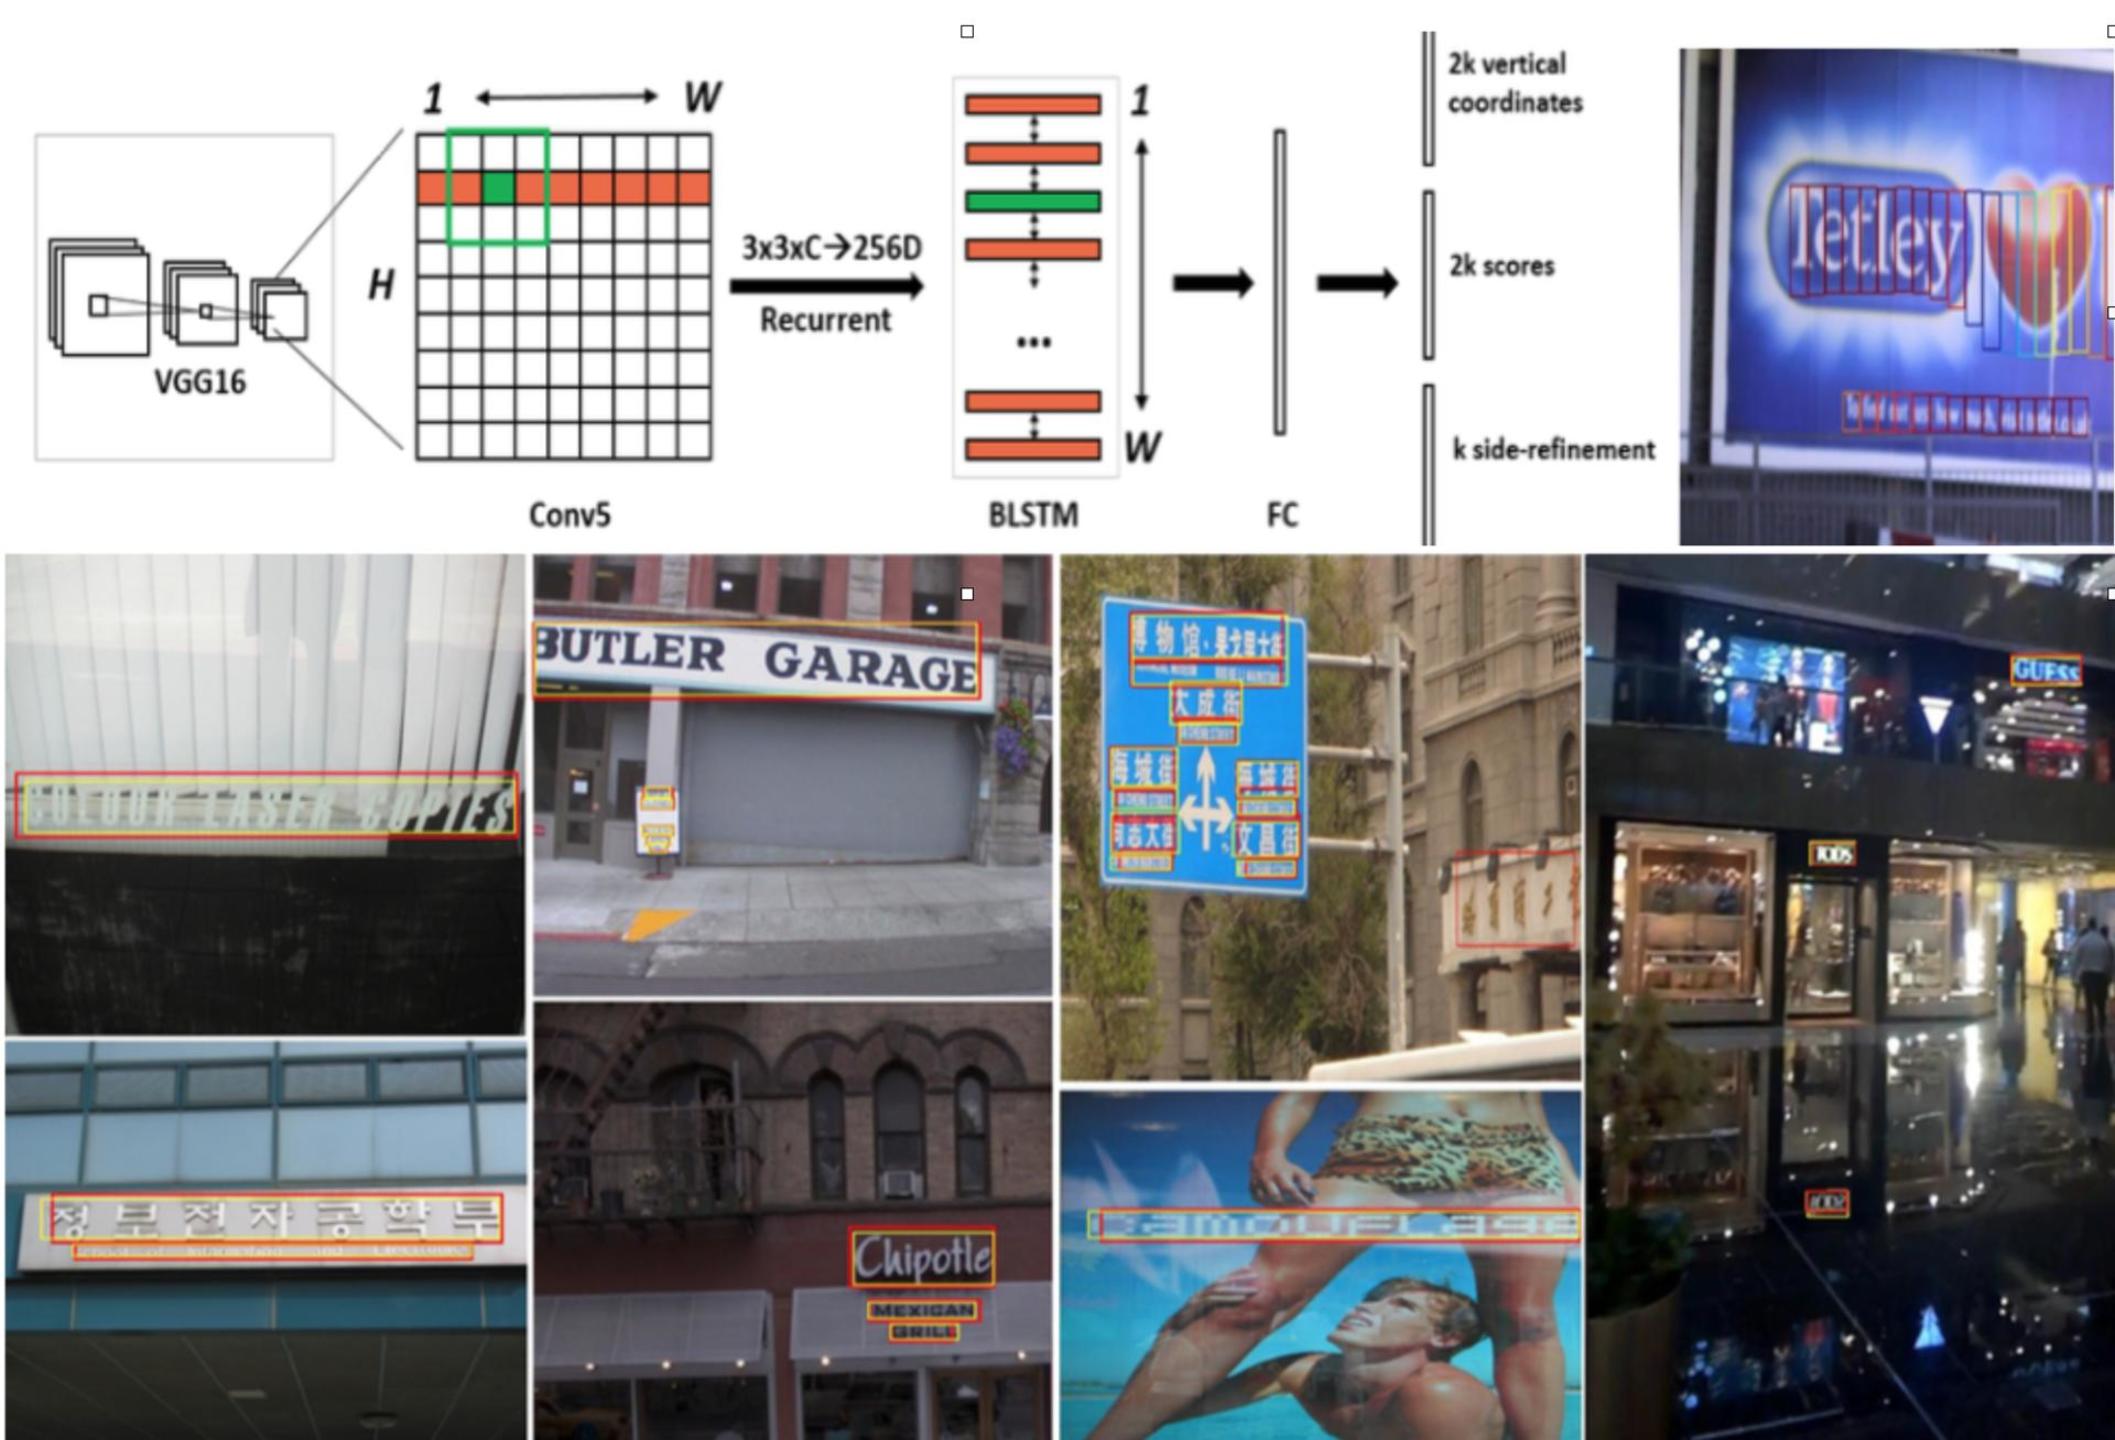
Detecting Text in Natural Image with Connectionist Text Proposal Network
European Conference on Computer Vision (ECCV), 2016
We propose a novel Connectionist Text Proposal Network (CTPN) that accurately localizes text lines in natural image. The CTPN detects a text line in a sequence of fine-scale text proposals directly in convolutional feature maps. We develop a vertical anchor mechanism that jointly predicts location and text/non-text score of each fixed-width proposal, considerably improving localization accuracy. The sequential proposals are naturally connected by a recurrent neural network, which is seamlessly incorporated into the convolutional network, resulting in an end-to-end trainable model. This allows the CTPN to explore rich context information of image, making it powerful to detect extremely ambiguous text. The CTPN works reliably on multi-scale and multilanguage text without further post-processing, departing from previous bottom-up methods requiring multi-step post filtering. It achieves 0.88 and 0.61 F-measure on the ICDAR 2013 and 2015 benchmarks, surpassing recent results [8, 35] by a large margin. The CTPN is computationally efficient with 0.14s/image, by using the very deep VGG16 model [27]. Online demo is available at: http://textdet.com/.
@inproceedings{tian2016detecting, title={Detecting text in natural image with connectionist text proposal network}, author={Tian, Zhi and Huang, Weilin and He, Tong and He, Pan and Qiao, Yu}, booktitle={European Conference on Computer Vision (ECCV)}, pages={56--72}, year={2016}, organization={Springer} }
Intelligent Transportation
-
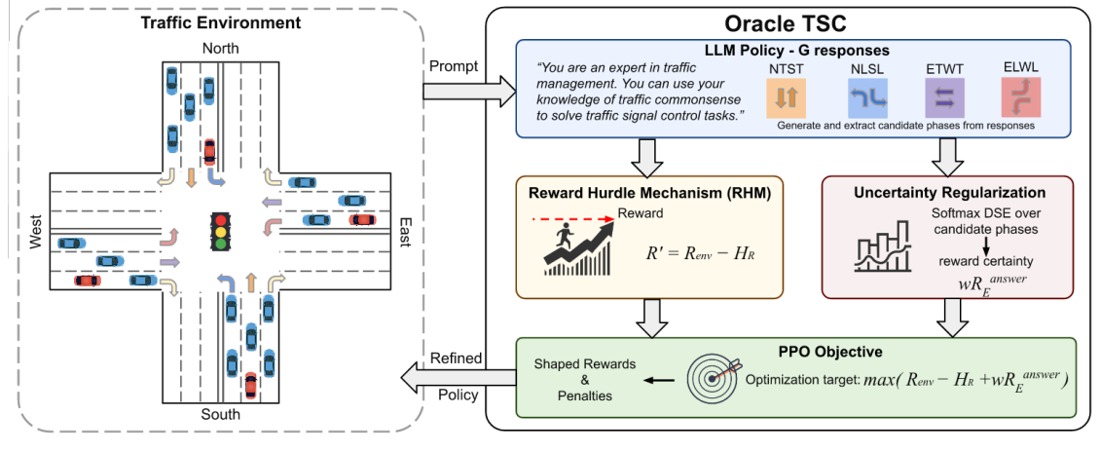
OracleTSC: Oracle-Informed Reward Hurdle and Uncertainty Regularization for Traffic Signal Control
Transactions on Machine Learning Research (TMLR), 2026
Transparent decision-making is essential for traffic signal control (TSC) systems to earn public trust. However, traditional reinforcement learning-based TSC methods function as black boxes with limited interpretability. Although large language models (LLMs) can provide natural language reasoning, reinforcement finetuning for TSC remains unstable because feedback is sparse and delayed, while most actions produce only marginal changes in congestion metrics. We introduce OracleTSC, which stabilizes LLM-based TSC through two mechanisms: (1) a reward hurdle mechanism that filters weak learning signals by subtracting a calibrated threshold from environmental rewards, and (2) uncertainty regularization that maximizes the probability of the selected response to encourage consistent decisions across sampled outputs. Experiments on the LibSignal benchmark show that OracleTSC enables a compact LLaMA3-8B model to substantially improve traffic efficiency, achieving a 75% reduction in travel time and a 67% decrease in queue length compared with the pretrained baseline while preserving interpretability through natural language explanations. OracleTSC also demonstrates strong cross-intersection generalization: a policy trained on one intersection transfers to a structurally different intersection with 17% lower travel time and 39% lower queue length without additional finetuning. These results suggest that uncertainty-aware reward shaping can improve the stability and effectiveness of reinforcement fine-tuning for TSC.
@article{panhe-oracletsc-2026, title = {OracleTSC: Oracle-Informed Reward Hurdle and Uncertainty Regularization for Traffic Signal Control}, author = {Darryl Jacob and Xinyu Liu and Muchao Ye and Xiaoyong Yuan and Pan He}, year = {2026}, journal = {Transactions on Machine Learning Research (TMLR)}, url = {https://openreview.net/forum?id=WmJu5MkoQD} } -
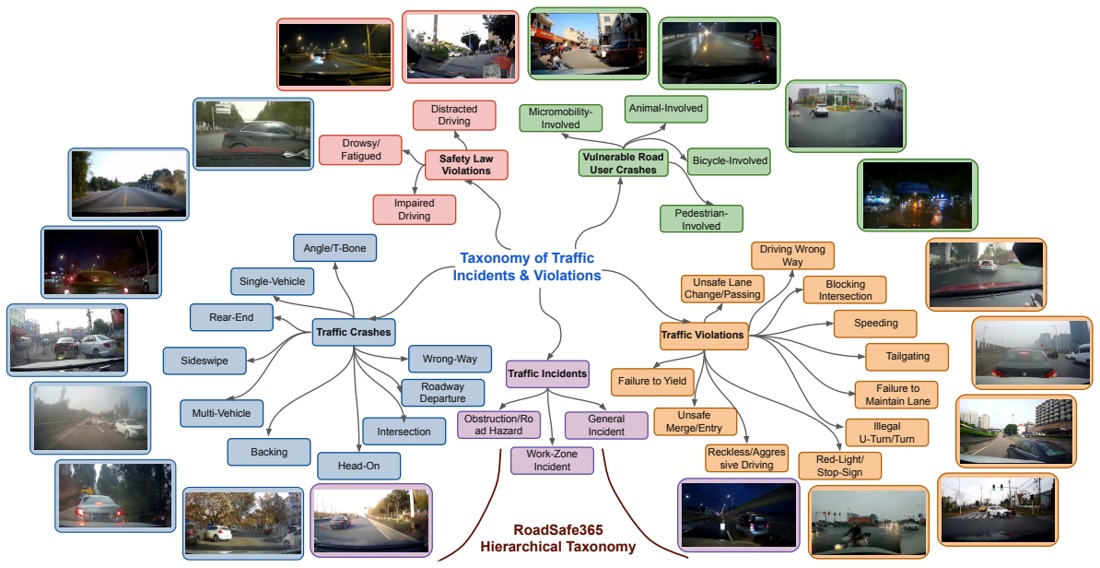
Understanding Real-World Traffic Safety through RoadSafe365 Benchmark
arXiv preprint, 2026
Although recent traffic benchmarks have advanced multimodal data analysis, they generally lack systematic evaluation aligned with official safety standards. To fill this gap, we introduce RoadSafe365, a large-scale vision-language benchmark that supports fine-grained analysis of traffic safety from extensive and diverse real-world video data collections. Unlike prior works that focus primarily on coarse accident identification, RoadSafe365 is independently curated and systematically organized using a hierarchical taxonomy that refines and extends foundational definitions of crash, incident, and violation to bridge official traffic safety standards with data-driven traffic understanding systems. RoadSafe365 provides rich attribute annotations across diverse traffic event types, environmental contexts, and interaction scenarios, yielding 36,196 annotated clips from both dashcam and surveillance cameras. Each clip is paired with multiple-choice question-answer sets, comprising 864K candidate options, 8.4K unique answers, and 36K detailed scene descriptions collectively designed for vision-language understanding and reasoning. We establish strong baselines and observe consistent gains when fine-tuning on RoadSafe365. Cross-domain experiments on both real and synthetic datasets further validate its effectiveness. Designed for large-scale training and standardized evaluation, RoadSafe365 provides a comprehensive benchmark to advance reproducible research in real-world traffic safety analysis.
@misc{panhe-roadsafe365-2026, title = {Understanding Real-World Traffic Safety through RoadSafe365 Benchmark}, author = {Xinyu Liu and Darryl Jacob and Yuxin Liu and Xinsong Du and Muchao Ye and Bolei Zhou and Pan He}, year = {2026}, note = {arXiv preprint, 2026}, url = {https://arxiv.org/abs/2602.07212} } -
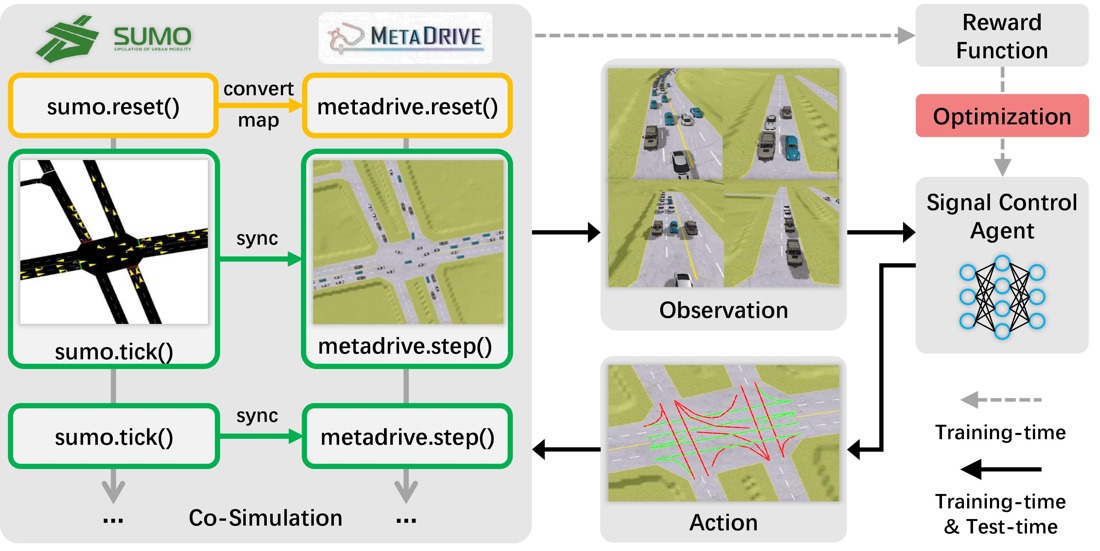
A Simple Framework Towards Vision-based Traffic Signal Control with Microscopic Simulation
105th Annual Meeting of the Transportation Research Board (TRB), 2026
Traffic signal control (TSC) is crucial for reducing traffic congestion leading to smoother traffic flow, reduced idle time, and mitigated CO2 emissions. In this paper, we explore the computer vision approach for TSC that modulates on-road traffic flows through visual observation. Unlike traditional feature-based approaches, vision-based methods depend much less on heuristics and predefined features, bringing promising potentials for end-to-end learning and optimization of traffic signals. Thus, we introduce a simple traffic simulation framework called TrafficDojo towards vision-based TSC and its benchmark by integrating the microscopic traffic flow provided in SUMO into the 3D driving simulator MetaDrive. This proposed framework offers a versatile traffic environment for in-depth analysis and comprehensive evaluation of traffic signal controllers across diverse traffic conditions and scenarios. We establish and compare baseline algorithms including both traditional and Reinforcement Learning (RL) approaches. This work sheds light on the design and development of vision-based TSC approaches and opens up new research opportunities
@inproceedings{panhe-trafficdojo-2026, title = {A Simple Framework Towards Vision-based Traffic Signal Control with Microscopic Simulation}, author = {Pan He and Quanyi Li and Xiaoyong Yuan and Bolei Zhou}, year = {2026}, booktitle = {105th Annual Meeting of the Transportation Research Board (TRB)}, url = {https://arxiv.org/abs/2403.06884} } -

Automated Truck Taxonomy Classification Using Deep Convolutional Neural Networks
International Journal of Intelligent Transportation Systems Research (IJIT), 2022
Trucks are the key transporters of freight. The types of commodities and goods mainly determine the right trailer for carrying them. Furthermore, fnding the commodities’ fow is an important task for transportation agencies in better planning freight infrastructure investments and initiating near-term trafc throughput improvements. In this paper, we propose a fnegrained deep learning based truck classifcation system that can detect and classify the trucks, tractors, and trailers following the Federal Highway Administration’s (FHWA) vehicle schema. We created a large, fne-grained labeled dataset of vehicle images collected from state highways. Experimental results show the high accuracy of our system and visualize the salient features of the trucks that infuence classifcation.
@article{almutairi2022automated, title={Automated Truck Taxonomy Classification Using Deep Convolutional Neural Networks}, author={Almutairi, Abdullah and He, Pan and Rangarajan, Anand and Ranka, Sanjay}, journal={International Journal of Intelligent Transportation Systems Research (IJIT)}, pages={1--12}, year={2022}, publisher={Springer} } -
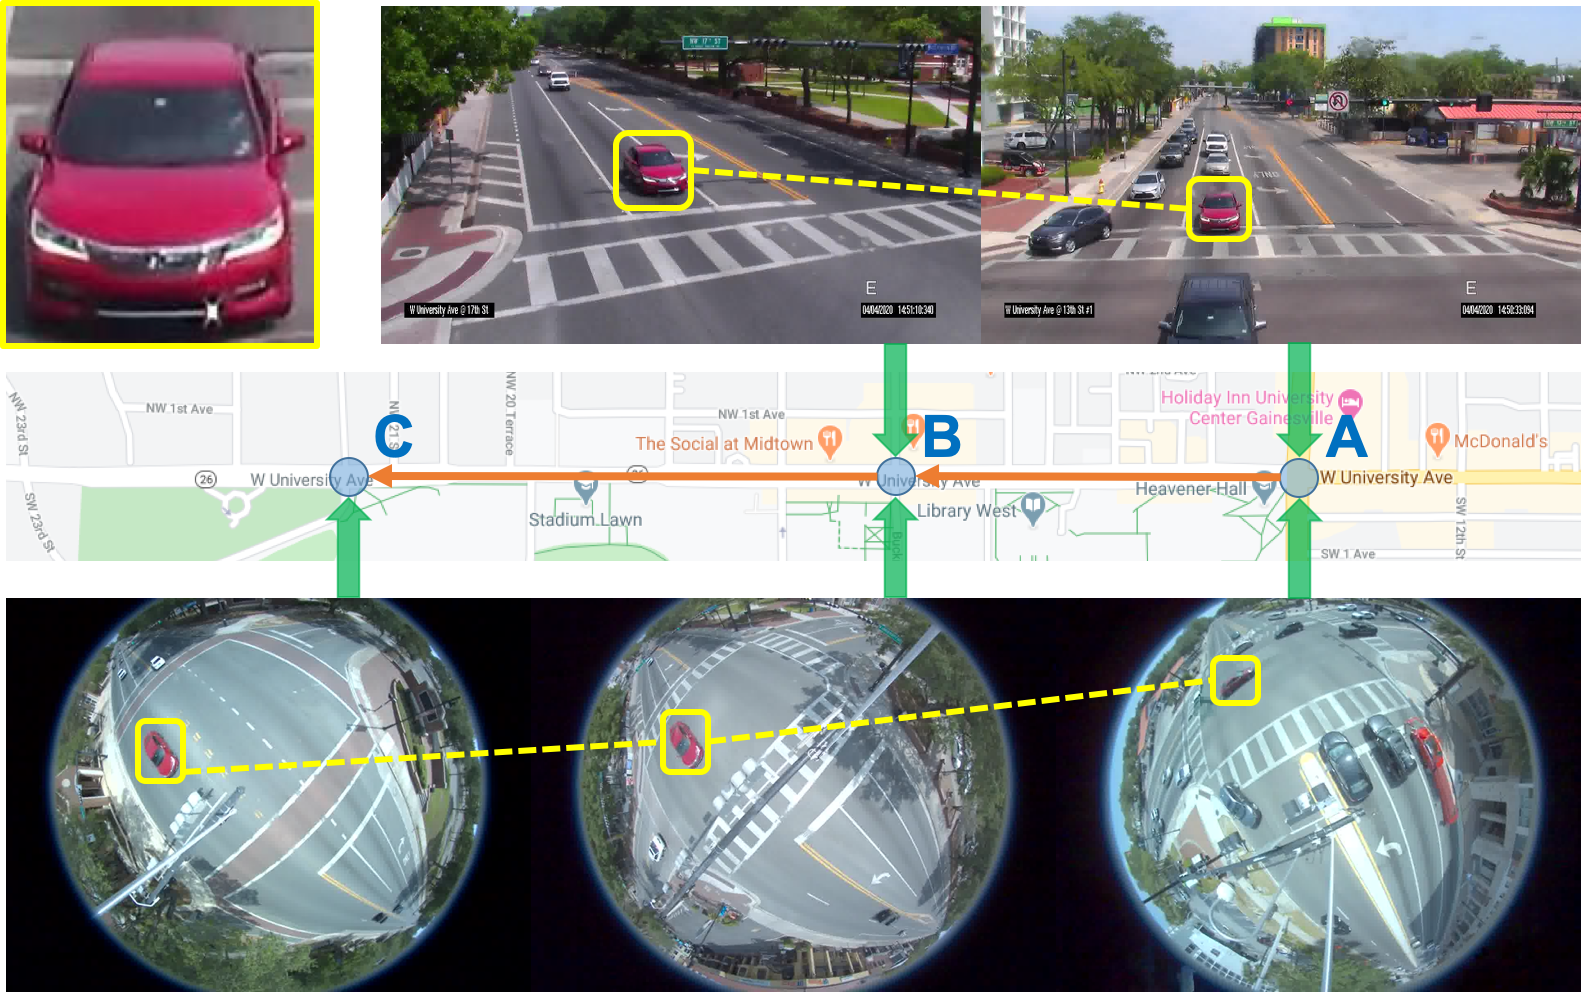
Machine Learning based Real-time Multi-Camera Vehicle Tracking and Travel Time Estimation
Journal of Imaging (J. Imaging), 2022
Travel-time estimation of traffic flow is an important problem with critical implications for traffic congestion analysis. We developed techniques for using intersection videos to identify vehicle trajectories across multiple cameras and analyze corridor travel time. Our approach consists of (1) multi-object single-camera tracking, (2) vehicle re-identification among different cameras, (3) multi-object multi-camera tracking, and (4) travel-time estimation. We evaluated the proposed framework on real intersections in Florida with pan and fisheye cameras. The experimental results demonstrate the viability and effectiveness of our method.
@article{huang2022machine, title={Machine-learning-based real-time multi-camera vehicle tracking and travel-time estimation}, author={Huang, Xiaohui and He, Pan and Rangarajan, Anand and Ranka, Sanjay}, journal={Journal of Imaging (J. Imaging)}, volume={8}, number={4}, pages={101}, year={2022}, publisher={MDPI} } -
Machine Learning-based Highway Truck Commodity Classification Using Logo Data
Applied Sciences (Appl. Sci.), 2022
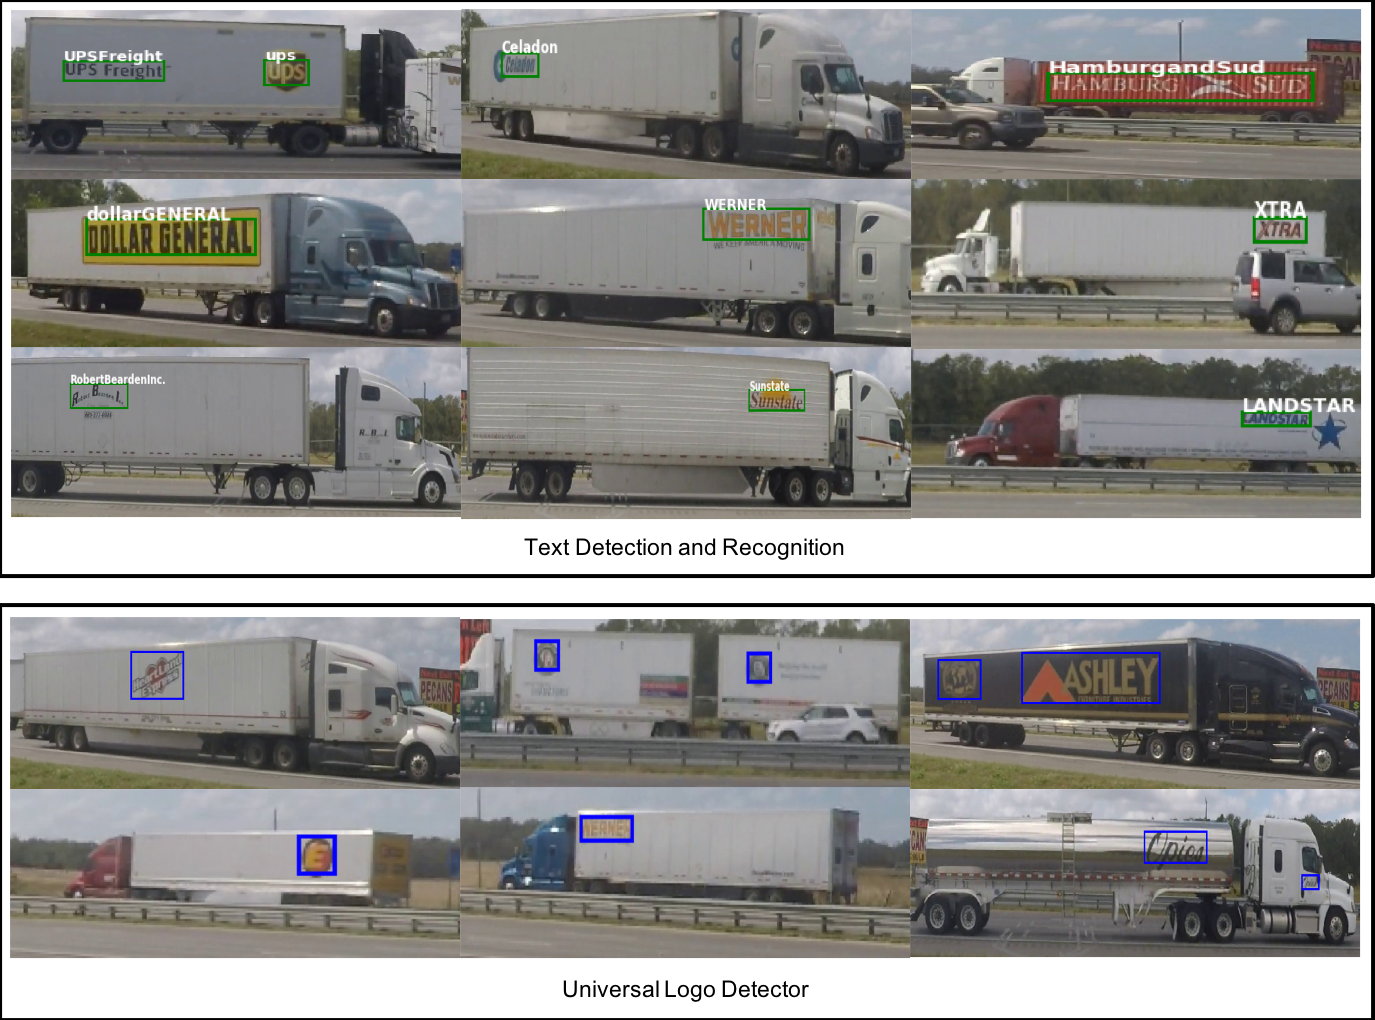
In this paper, we propose a novel approach to commodity classification from surveillance videos by utilizing logo data on trucks. Broadly, most logos can be classified as predominantly text or predominantly images. For the former, we leverage state-of-the-art deep-learning-based text recognition algorithms on images. For the latter, we develop a two-stage image retrieval algorithm consisting of a universal logo detection stage that outputs all potential logo positions, followed by a logo recognition stage designed to incorporate advanced image representations. We develop an integrated approach to combine predictions from both the text-based and image-based solutions, which can help determine the commodity type that is potentially being hauled by trucks. We evaluated these models on videos collected in collaboration with the state transportation entity and achieved promising performance. This, along with prior work on trailer classification, can be effectively used for automatically deriving commodity types for trucks moving on highways.
@article{he2022machine, title={Machine Learning-Based Highway Truck Commodity Classification Using Logo Data}, author={He, Pan and Wu, Aotian and Huang, Xiaohui and Rangarajan, Anand and Ranka, Sanjay}, journal={Applied Sciences (Appl. Sci.)}, volume={12}, number={4}, pages={2075}, year={2022}, publisher={MDPI} } -
Video-based Machine Learning System for Commodity Classification
International Conference on Vehicle Technology and Intelligent Transport Systems (VEHITS), 2020
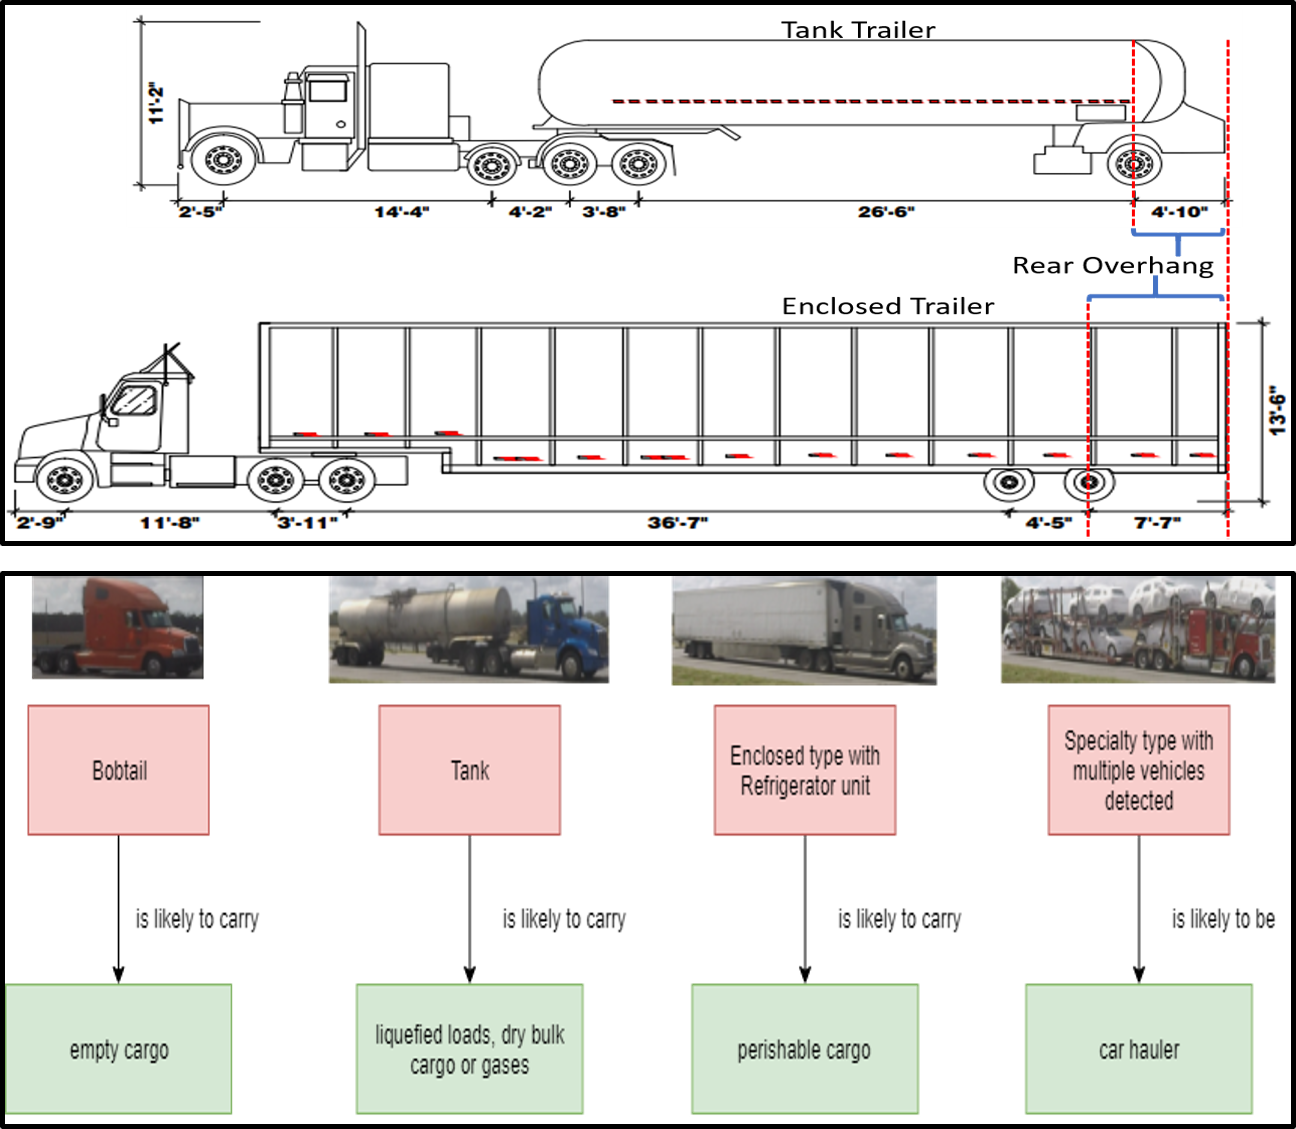
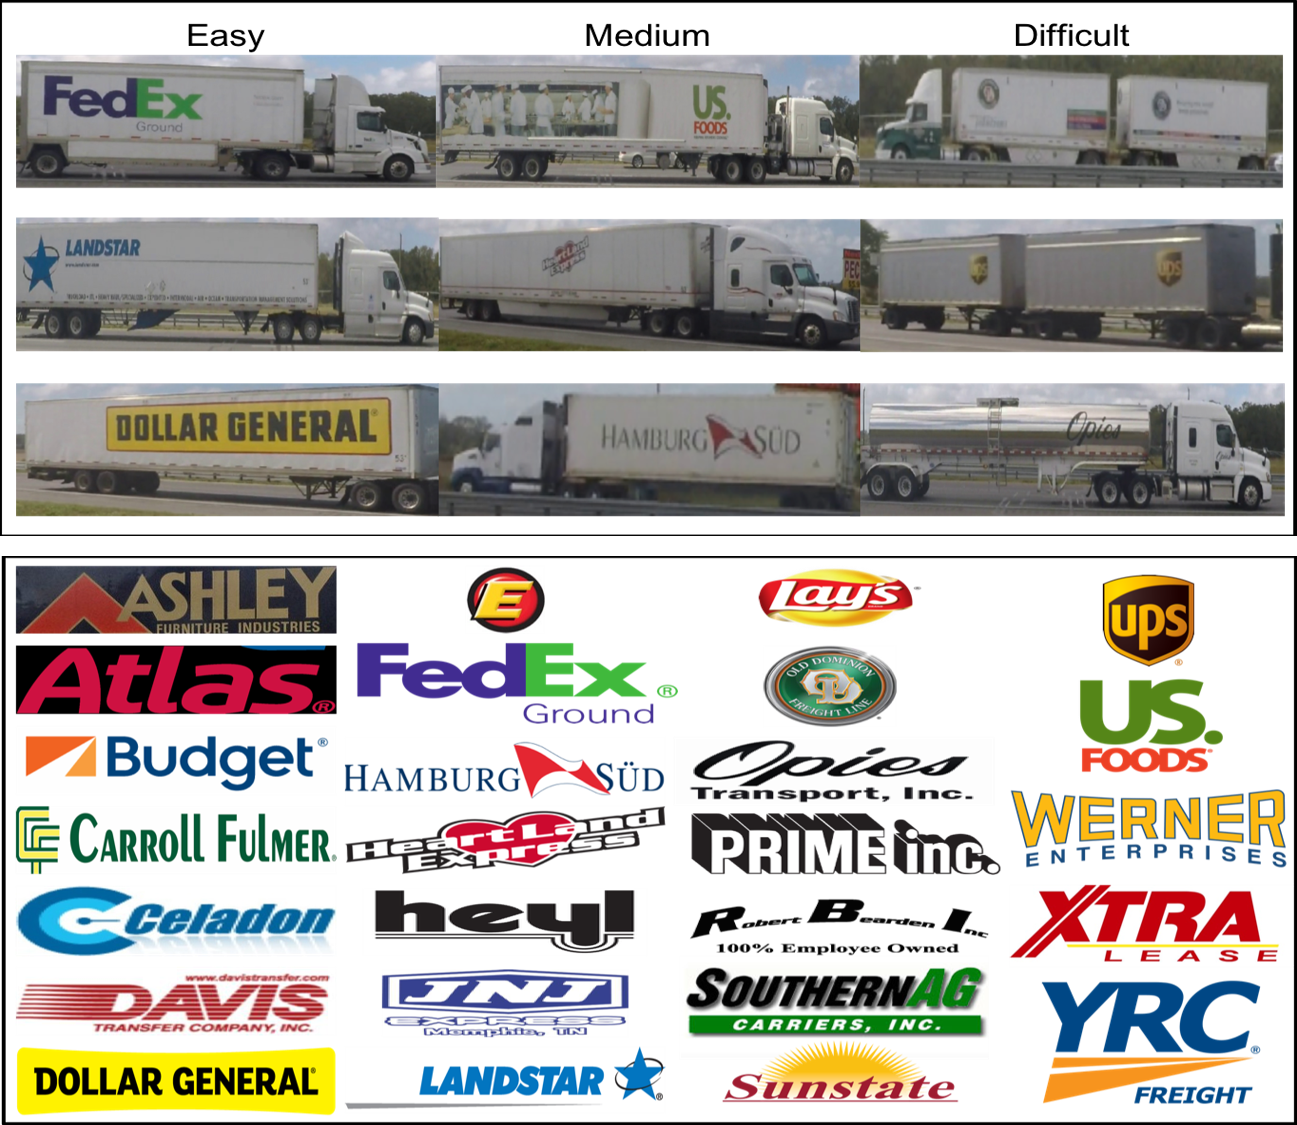
The cost of video cameras is decreasing rapidly while their resolution is improving. This makes them useful for a number of transportation applications. In this paper, we present an approach to commodity classification from surveillance videos by utilizing text information of logos on trucks. A new real-world benchmark dataset is collected and annotated accordingly that covers over 4,000 truck images. Our approach is evaluated on video data collected in collaboration with the state transportation entity. Results on this dataset indicate that our proposed approach achieved promising performance. This, along with prior work on trailer classification, can be effectively used for automatically deriving the commodity classification for trucks moving on highways using video collection and processing.
@inproceedings{he2020video, title={Video-based Machine Learning System for Commodity Classification}, author={He, Pan and Wu, Aotian and Huang, Xiaohui and Rangarajan, Anand and Ranka, Sanjay}, booktitle={International Conference on Vehicle Technology and Intelligent Transport Systems (VEHITS)}, year={2020} } -
Truck and Trailer Classification with Deep Learning based Geometric Features
IEEE Transactions on Intelligent Transportation Systems (T-ITS), 2019
In this paper, we present a novel and effective approach to truck and trailer classification, which integrates deep learning models and conventional image processing and computer vision techniques. The developed method groups trucks into subcategories by carefully examining the truck classes and identifying key geometric features for discriminating truck and trailer types. We also present three discriminating features that involve shape, texture, and semantic information to identify trailer types. Experimental results demonstrate that the developed hybrid approach can achieve high accuracy with limited training data, where the vanilla deep learning approaches show moderate performance due to over-fitting and poor generalization. Additionally, the models generated are human-understandable.
@article{he2020truck, title={Truck and Trailer Classification With Deep Learning Based Geometric Features}, author={He, Pan and Wu, Aotian and Huang, Xiaohui and Scott, Jerry and Rangarajan, Anand and Ranka, Sanjay}, journal={IEEE Transactions on Intelligent Transportation Systems (T-ITS)}, year={2020}, publisher={IEEE} } -
Deep Learning based Geometric Features for Effective Truck Selection and Classification from Highway Videos
IEEE Intelligent Transportation Systems Conference (ITSC), 2019
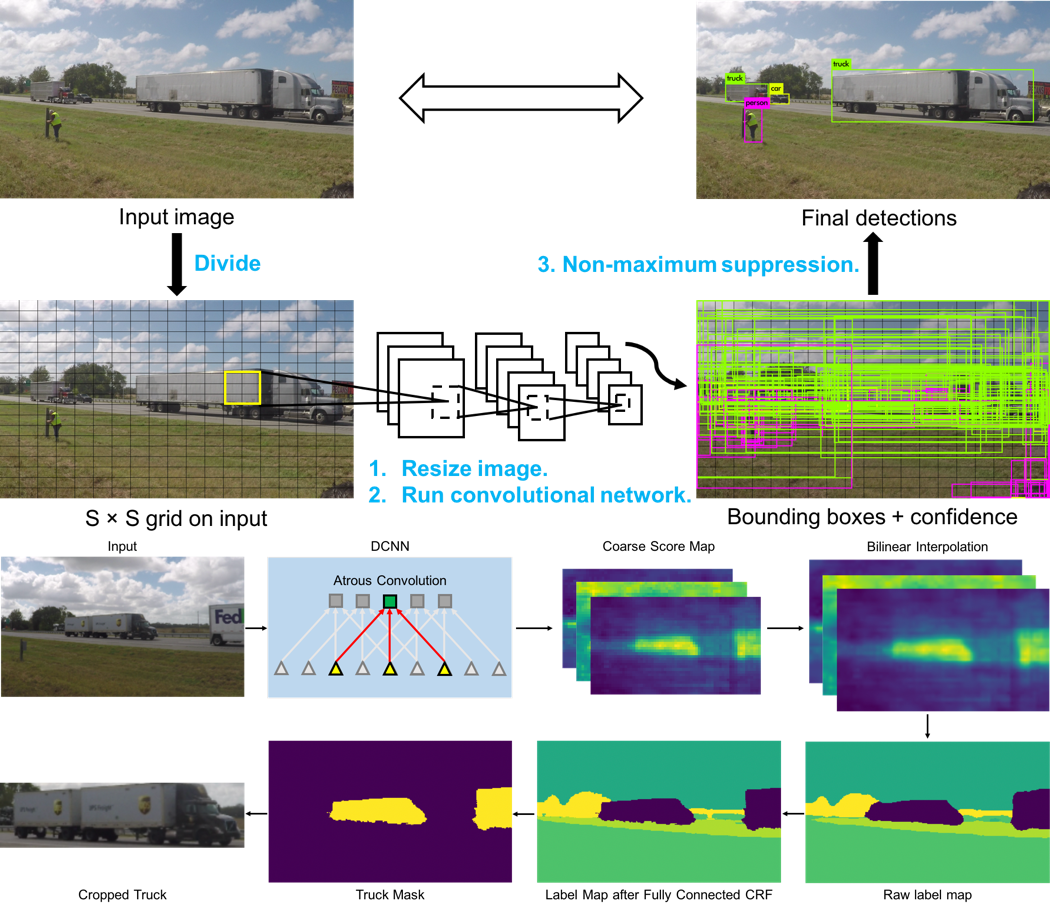
Freight analysis creates a comprehensive picture of freight movements across the state (and country), by capturing and gathering a variety of sources. Understanding and predicting freight flow patterns is useful in planning and policy decisions at the federal, state, and local levels. Trucks are largely in charge of transporting freight, both in terms of tonnage and revenue. The Federal Highway Administration (FHWA) has a methodology for classifying these trucks into nine categories. Determining the class of the truck is useful in understanding the type of commodity that truck is carrying. This paper details a video based machine learning approach for truck classification. Our approach uses an array of techniques from image processing, deep learning and data mining to develop highly accurate classifiers. Additionally, we provide mechanisms for automatically filtering out trucks from video data.
@inproceedings{he2019deep, title={Deep Learning based Geometric Features for Effective Truck Selection and Classification from Highway Videos}, author={He, Pan and Wu, Aotian and Huang, Xiaohui and Scott, Jerry and Rangarajan, Anand and Ranka, Sanjay}, booktitle={IEEE Intelligent Transportation Systems Conference (ITSC)}, pages={824--830}, year={2019}, organization={IEEE} } -
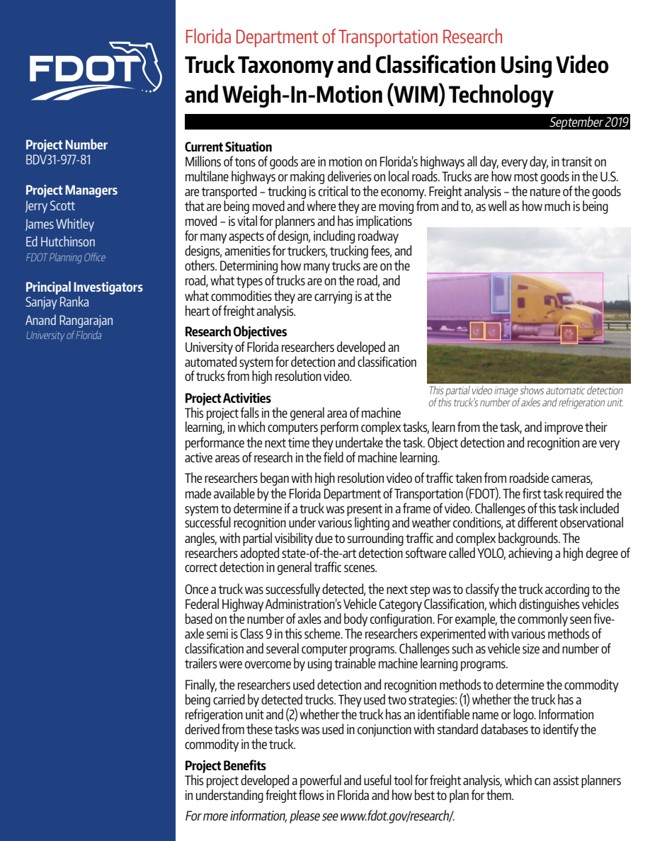
Truck Taxonomy and Classification Using Video and Weigh-In Motion (WIM) Technology Final Report
Final research report, Florida Department of Transportation, 2019
@misc{panhe-scholar-41, title = {{Truck Taxonomy and Classification Using Video and Weigh-In Motion (WIM) Technology Final Report}}, author = {Pan He and Aotian Wu and Anand Rangarajan and Sanjay Ranka}, year = {2019}, note = {Final research report, Florida Department of Transportation, 2019}, url = {https://rosap.ntl.bts.gov/view/dot/62977} } -
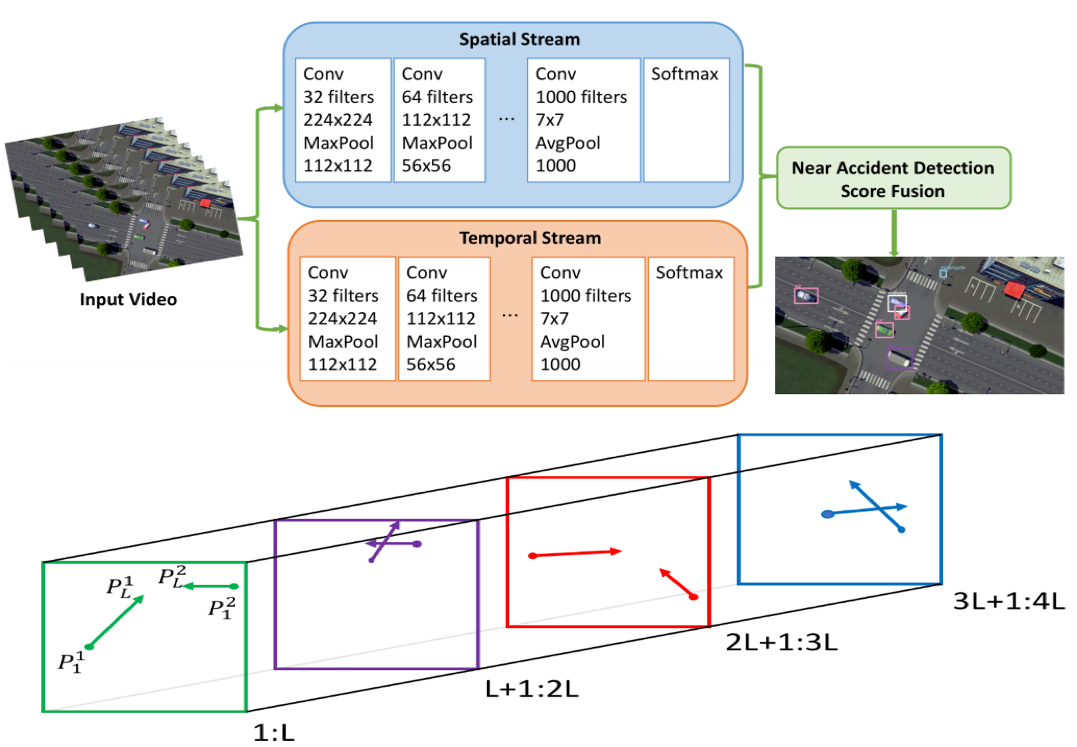
Intelligent Intersection: Two-Stream Convolutional Networks for Real-time Near Accident Detection in Traffic Video
ACM Transactions on Spatial Algorithms and Systems (TSAS), 2018
In Intelligent Transportation System, real-time systems that monitor and analyze road users become increasingly critical as we march toward the smart city era. Vision-based frameworks for Object Detection, Multiple Object Tracking, and Traffic Near Accident Detection are important applications of Intelligent Transportation System, particularly in video surveillance and etc. Although deep neural networks have recently achieved great success in many computer vision tasks, a uniformed framework for all the three tasks is still challenging where the challenges multiply from demand for real-time performance, complex urban setting, highly dynamic traffic event, and many traffic movements. In this paper, we propose a two-stream Convolutional Network architecture that performs real-time detection, tracking, and near accident detection of road users in traffic video data. The two-stream model consists of a spatial stream network for Object Detection and a temporal stream network to leverage motion features for Multiple Object Tracking. We detect near accidents by incorporating appearance features and motion features from two-stream networks. Using aerial videos, we propose a Traffic Near Accident Dataset (TNAD) covering various types of traffic interactions that is suitable for vision-based traffic analysis tasks. Our experiments demonstrate the advantage of our framework with an overall competitive qualitative and quantitative performance at high frame rates on the TNAD dataset.
@article{huang2020intelligent, title={Intelligent intersection: two-stream convolutional networks for real-time near-accident detection in traffic video}, author={Huang, Xiaohui and He, Pan and Rangarajan, Anand and Ranka, Sanjay}, journal={ACM Transactions on Spatial Algorithms and Systems (TSAS)}, volume={6}, number={2}, pages={1--28}, year={2020}, publisher={ACM New York, NY, USA} }
Neural Networks and Constraints
-
Preview pending
Expressing Linear Equality Constraints in Feedforward Neural Networks
arXiv:2211.04395
We seek to impose linear, equality constraints in feedforward neural networks. As top layer predictors are usually nonlinear, this is a difficult task if we seek to deploy standard convex optimization methods and strong duality. To overcome this, we introduce a new saddle-point Lagrangian with auxiliary predictor variables on which constraints are imposed. Elimination of the auxiliary variables leads to a dual minimization problem on the Lagrange multipliers introduced to satisfy the linear constraints. This minimization problem is combined with the standard learning problem on the weight matrices. From this theoretical line of development, we obtain the surprising interpretation of Lagrange parameters as additional, penultimate layer hidden units with fixed weights stemming from the constraints. Consequently, standard minimization approaches can be used despite the inclusion of Lagrange parameters -- a very satisfying, albeit unexpected, discovery. Examples ranging from multi-label classification to constrained autoencoders are envisaged in the future.
@article{rangarajan2022expressing, title={Expressing linear equality constraints in feedforward neural networks}, author={Rangarajan, Anand and He, Pan and Lee, Jaemoon and Banerjee, Tania and Ranka, Sanjay}, journal={arXiv:2211.04395}, year={2022} },
Books, Patents, and Dissertation
-
Preview pending
Deep Learning on Spatiotemporal Point Cloud Modeling for Motion and Correspondence
Ph.D. dissertation, University of Florida, 2023
@misc{panhe-scholar-20, title = {{Deep Learning on Spatiotemporal Point Cloud Modeling for Motion and Correspondence}}, author = {Pan He}, year = {2023}, note = {Ph.D. dissertation, University of Florida, 2023}, url = {https://www.proquest.com/docview/2881074257} } -
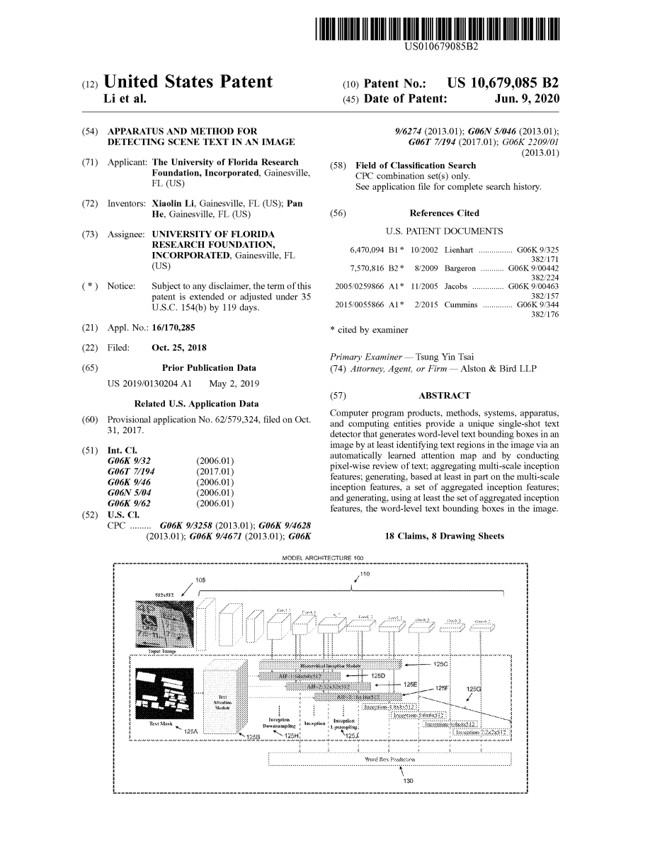
Apparatus and Method for Detecting Scene Text in An Image
US Patent 10,679,085 B2, granted June 9, 2020
Computer program products, methods, systems, apparatus, and computing entities provide a unique single-shot text detector that generates word-level text bounding boxes in an image by at least identifying text regions in the image via an automatically learned attention map and by conducting pixel-wise review of text; aggregating multi-scale inception features; generating, based at least in part on the multi-scale inception features, a set of aggregated inception features; and generating, using at least the set of aggregated inception features, the word-level text bounding boxes in the image.
@misc{panhe-scholar-34, title = {{Apparatus and Method for Detecting Scene Text in An Image}}, author = {Xiaolin Li and Pan He}, year = {2020}, note = {US Patent 10,679,085, 2020}, url = {https://patents.google.com/patent/US10679085B2/en} } -
Dive into OCR: Scene Text Understanding with Deep Learning
Book, China Machine Press (CMP), 2020
@misc{panhe-scholar-36, title = {{Dive into OCR: Scene Text Understanding with Deep Learning}}, author = {Shuchun Liu and Pan He and Jianqi Ma and Jiajun Wang and Yufei Xie and Mingxi Chen}, year = {2020}, note = {Book, China Machine Press, 2020}, url = {http://product.dangdang.com/28548394.html} } -
Methods and Apparatus for Recognizing Text in An Image
Published PCT application WO2016197381A1, December 15, 2016
@misc{panhe-scholar-49,
  title = {{Methods and Apparatus for Recognizing Text in An Image}},
  author = {Xiaoou Tang and Weilin Huang and Yu Qiao and Chen Change Loy and Pan He},
  year = {2016},
  note = {Published PCT application WO2016197381A1, December 15, 2016},
  url = {resources/WO2016197381A1.pdf}
}